X3A: Efficient Multimodal Deepfake Detection with Score-Level Fusion
- In partial deepfakes, only a fraction of a second of face or voice is altered; many detectors miss it.
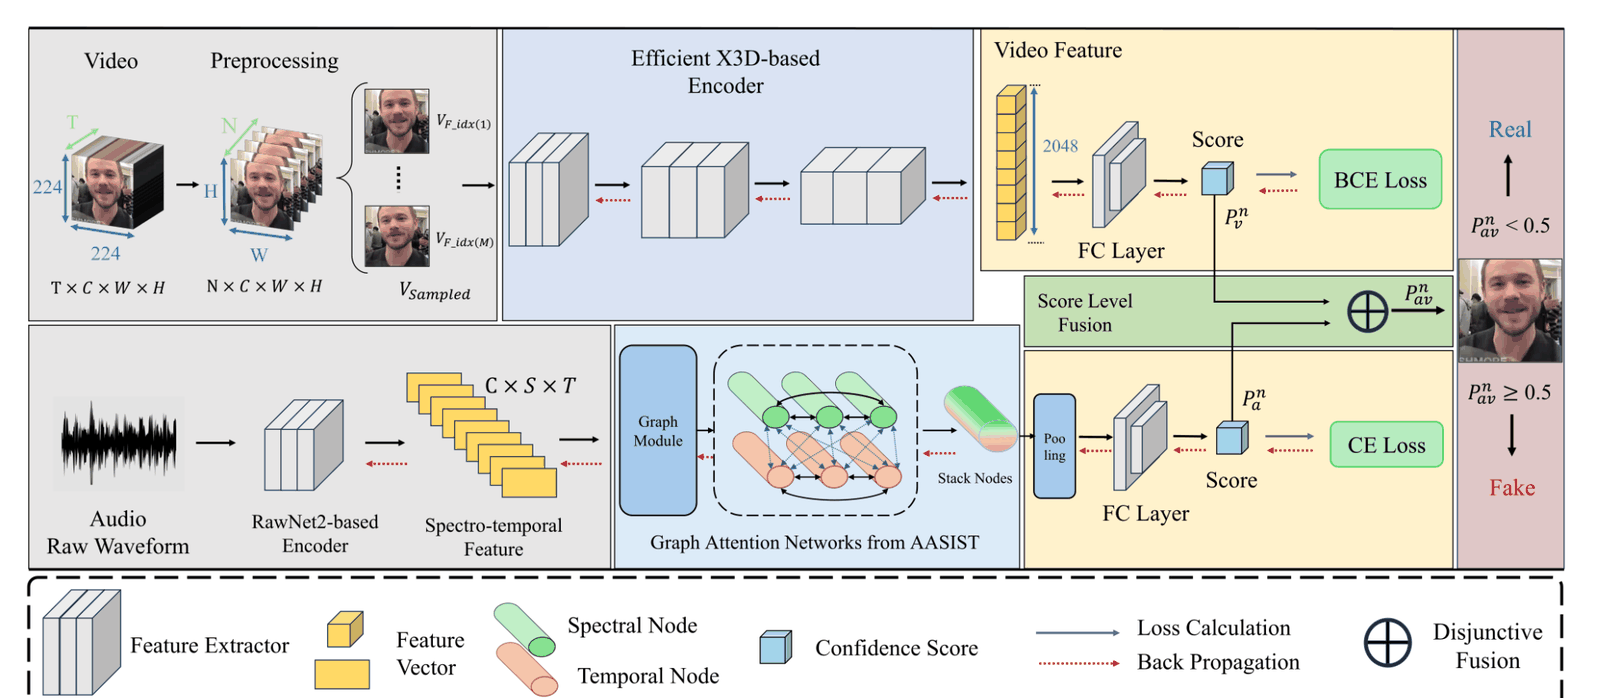
- X3A runs X3D on raw frames and AASIST on the raw waveform, then fuses their scores with a probabilistic OR.
- On AV-Deepfake1M: AUC 0.9999 and accuracy 0.9960, the highest among methods compared in the paper.
- 부분 딥페이크는 얼굴이나 목소리의 1초도 안 되는 구간만 바꿔, 많은 탐지기가 놓칩니다.
- X3A는 원본 프레임에 X3D를, 원본 파형에 AASIST를 적용하고, 두 점수를 확률적 OR로 결합합니다.
- AV-Deepfake1M에서 AUC 0.9999, 정확도 0.9960으로 논문의 비교 방법 중 최고입니다.
- 部分深度伪造只篡改人脸或声音中不到一秒的片段,许多检测器难以发现。
- X3A 用 X3D 处理原始视频帧,用 AASIST 处理原始音频波形,再以概率 OR 融合两者分数。
- 在 AV-Deepfake1M 上 AUC 0.9999、准确率 0.9960,在论文对比方法中最高。
In one line: two strong single-modality detectors, one for video and one for audio, each give a fake score; a probabilistic OR combines them.
SSituation
- Newer benchmarks (LAV-DF, AV-Deepfake1M) contain partial audio-visual deepfakes.
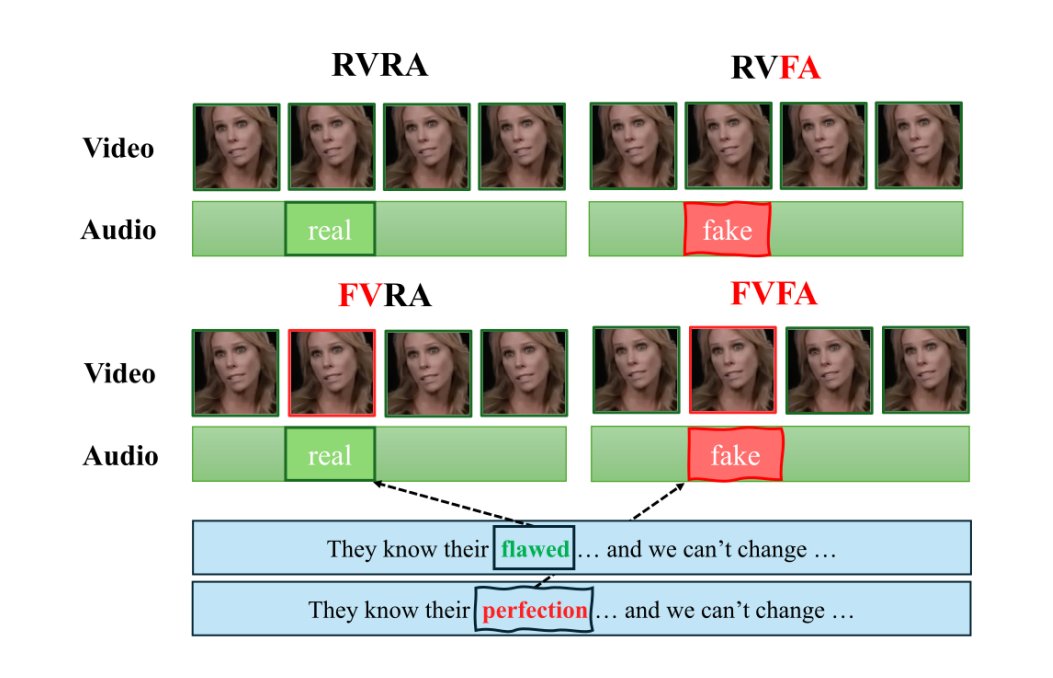
- Only a few spoken words and the matching lip movements are re-generated. The rest stays real.
- In AV-Deepfake1M, a fake segment lasts only 0.326 seconds on average.
- Frame-level detectors need per-frame labels and ignore temporal context.
- Detectors trained on fully fake videos, such as Self-Blended Images (SBI), miss these short edits.
- Many video-level detectors add hand-crafted inputs such as optical flow. That means heavy preprocessing.
한 줄 요약: 비디오용과 오디오용 단일 모달리티 탐지기가 각각 가짜 점수를 내고, 확률적 OR로 두 점수를 결합합니다.
S상황
- LAV-DF, AV-Deepfake1M 같은 최신 벤치마크에는 부분 오디오-비주얼 딥페이크가 들어 있습니다.
- 말의 몇 단어와 그에 맞는 입 모양만 다시 생성하고, 나머지는 진짜 그대로입니다.
- AV-Deepfake1M에서 가짜 구간의 평균 길이는 0.326초에 불과합니다.
- 프레임 단위 탐지기는 프레임별 라벨이 필요하고 시간적 맥락을 놓칩니다.
- Self-Blended Images(SBI)처럼 완전 조작 영상으로 학습한 탐지기는 이런 짧은 조작을 놓칩니다.
- 많은 비디오 단위 탐지기는 optical flow 같은 수작업 입력을 추가해 전처리 비용이 큽니다.
一句话概括:视频和音频各用一个强大的单模态检测器输出伪造分数,再用概率 OR 融合两者。
S情境
- LAV-DF、AV-Deepfake1M 等新基准包含部分音视频深度伪造。
- 只重新生成少数几个词及对应的唇部动作,其余部分保持真实。
- AV-Deepfake1M 中伪造片段平均只有 0.326 秒。
- 帧级检测器需要逐帧标签,且忽略时间上下文。
- 在完全伪造视频上训练的检测器(如 Self-Blended Images,SBI)会漏掉这类短暂篡改。
- 许多视频级检测器额外使用 optical flow 等手工输入,预处理开销大。
TTask
- Label the whole video real or fake, whether the edit is in the video, the audio, or both.
- Use only raw frames and the raw waveform: no hand-crafted features, so the pipeline stays simple and efficient.
T과제
- 조작이 비디오·오디오·둘 다 중 어디에 있든, 영상 전체를 진짜/가짜로 판별한다.
- 원본 프레임과 원본 파형만 사용한다. 수작업 특징이 없어 파이프라인이 단순하고 효율적이다.
T任务
- 无论篡改位于视频、音频还是两者,都对整段视频判定真伪。
- 只使用原始帧和原始波形,不用手工特征,使流程简单高效。
AAction
- Visual stream (X3D). X3D is an efficient action-recognition 3D CNN.
- It reads 128 uniformly sampled frames, about 57% of an AV-Deepfake1M video on average.
- Seeing the whole clip at once helps it catch short, subtle edits.
- An MLP head outputs the visual fake score Pv.
- Audio stream (AASIST). An anti-spoofing model that works end-to-end on the raw waveform.
- A RawNet2 encoder feeds graph attention over spectral and temporal features.
- Maximum-length padding keeps every fake segment inside the input.
- It outputs the audio fake score Pa.
- Score-level fusion (probabilistic OR). Pav = 1 − (1 − Pv)(1 − Pa).
- A video is flagged fake if either stream finds it fake.
- We compared three rules: probabilistic OR, a decision-level OR gate, and max. We chose probabilistic OR because it reduced false positives.
- The streams run independently, so no cross-modal feature alignment is needed.
- Strict evaluation. Test sets of FakeAVCeleb, AV-Deepfake1M and LAV-DF contain only unseen speakers.
- AV-Deepfake1M has no labeled test set, so we merged its train and validation sets and re-split them by speaker.
A행동
- 비디오 스트림 (X3D). X3D는 효율적인 행동 인식용 3D CNN입니다.
- 균일하게 뽑은 128프레임을 읽습니다. AV-Deepfake1M 영상 기준 평균 약 57%입니다.
- 클립 전체를 한 번에 보므로 짧고 미묘한 조작도 잡아냅니다.
- MLP 헤드가 비디오 가짜 점수 Pv를 출력합니다.
- 오디오 스트림 (AASIST). 원본 파형에서 종단간으로 동작하는 음성 위조 탐지(anti-spoofing) 모델입니다.
- RawNet2 인코더 출력에 스펙트럼·시간 특징 그래프 어텐션을 적용합니다.
- 최대 길이 패딩으로 가짜 구간이 입력에서 잘리지 않게 했습니다.
- 오디오 가짜 점수 Pa를 출력합니다.
- 점수 단위 결합 (확률적 OR). Pav = 1 − (1 − Pv)(1 − Pa).
- 어느 한 스트림이라도 가짜로 판단하면 영상을 가짜로 판정합니다.
- 확률적 OR, 결정 단위 OR 게이트, max 세 규칙을 비교했고, 오탐을 줄여 주는 확률적 OR을 택했습니다.
- 두 스트림이 독립적으로 동작하므로 모달리티 간 특징 정렬이 필요 없습니다.
- 엄격한 평가. FakeAVCeleb, AV-Deepfake1M, LAV-DF의 테스트셋은 모두 처음 보는 화자로만 구성했습니다.
- AV-Deepfake1M은 라벨이 있는 테스트셋이 없어, 학습·검증셋을 합친 뒤 화자 기준으로 다시 나눴습니다.
A行动
- 视频流(X3D)。X3D 是高效的动作识别 3D CNN。
- 读取均匀采样的 128 帧,平均约占 AV-Deepfake1M 视频的 57%。
- 一次看完整个片段,有助于捕捉短而细微的篡改。
- MLP 头输出视频伪造分数 Pv。
- 音频流(AASIST)。直接在原始波形上端到端工作的反欺骗(anti-spoofing)模型。
- RawNet2 编码器的输出送入频谱与时间特征上的图注意力。
- 最大长度填充确保伪造片段不会被截掉。
- 输出音频伪造分数 Pa。
- 分数级融合(概率 OR)。Pav = 1 − (1 − Pv)(1 − Pa)。
- 任一路判为伪造,整段视频即判为伪造。
- 比较了概率 OR、决策级 OR 门和 max 三种规则,概率 OR 误报更少,因此被采用。
- 两路相互独立,无需跨模态特征对齐。
- 严格评估。FakeAVCeleb、AV-Deepfake1M 和 LAV-DF 的测试集只包含未见过的说话人。
- AV-Deepfake1M 没有带标签的测试集,因此将训练集与验证集合并后按说话人重新划分。
RResult
- AV-Deepfake1M (partial edits): AUC 0.9999, accuracy 0.9960. Highest among methods compared in the paper (next: MMMS-BA, 0.9790 / 0.9680).
- LAV-DF: AUC 0.9999, highest in the comparison. Accuracy 0.9976, on par with FMDC (0.9998 / 0.9981).
- FakeAVCeleb (fully fake): AUC 0.9968 / accuracy 0.9890, second to FMDC (0.9994 / 0.9984).
- Each stream is strong alone (Tables 1–2 below). X3D reaches AUC 0.9999 on the AV-Deepfake1M and LAV-DF visual subsets. AASIST reaches AUC 1.0000 on all three audio subsets.
- Takeaway: a simple late-fusion design comes close to the best fusion model compared.
- Limits noted in the paper: no cross-dataset evaluation yet, and no temporal localization of the fake segment.
- ACM SAC 2025 (equal-contribution first author). Korean software copyright “Efficient Multimodal Deepfake Detection with Score-Level Fusion” registered in 2025.
R결과
- AV-Deepfake1M(부분 조작): AUC 0.9999, 정확도 0.9960. 논문의 비교 방법 중 최고입니다(차순위 MMMS-BA 0.9790 / 0.9680).
- LAV-DF: AUC 0.9999로 비교 방법 중 최고, 정확도 0.9976으로 FMDC(0.9998 / 0.9981)와 대등합니다.
- FakeAVCeleb(전체 조작): AUC 0.9968 / 정확도 0.9890으로 FMDC(0.9994 / 0.9984)에 이어 2위입니다.
- 각 스트림도 단독으로 강합니다(아래 표 1–2). X3D는 AV-Deepfake1M·LAV-DF 비디오 부분집합에서 AUC 0.9999, AASIST는 세 오디오 부분집합 모두에서 AUC 1.0000입니다.
- 시사점: 단순한 후기 결합 설계로도 비교 대상 중 최고 결합 모델에 근접했습니다.
- 논문이 밝힌 한계: 교차 데이터셋 평가가 아직 없고, 가짜 구간의 시간적 위치(temporal localization)는 찾지 않습니다.
- ACM SAC 2025 공동 제1저자 논문. 2025년 국내 소프트웨어 저작권(“Efficient Multimodal Deepfake Detection with Score-Level Fusion”) 등록.
R结果
- AV-Deepfake1M(部分篡改):AUC 0.9999,准确率 0.9960,在论文对比方法中最高(次佳 MMMS-BA:0.9790 / 0.9680)。
- LAV-DF:AUC 0.9999,对比中最高;准确率 0.9976,与 FMDC(0.9998 / 0.9981)相当。
- FakeAVCeleb(完全篡改):AUC 0.9968 / 准确率 0.9890,仅次于 FMDC(0.9994 / 0.9984)。
- 单路也很强(见下方表 1–2):X3D 在 AV-Deepfake1M 和 LAV-DF 的视频子集上 AUC 达 0.9999;AASIST 在三个音频子集上 AUC 均为 1.0000。
- 结论:简单的后期融合设计已接近对比中最好的融合模型。
- 论文指出的局限:尚未做跨数据集评估,也不定位伪造片段的时间位置(temporal localization)。
- 发表于 ACM SAC 2025(共同第一作者);2025 年登记韩国软件著作权「Efficient Multimodal Deepfake Detection with Score-Level Fusion」。
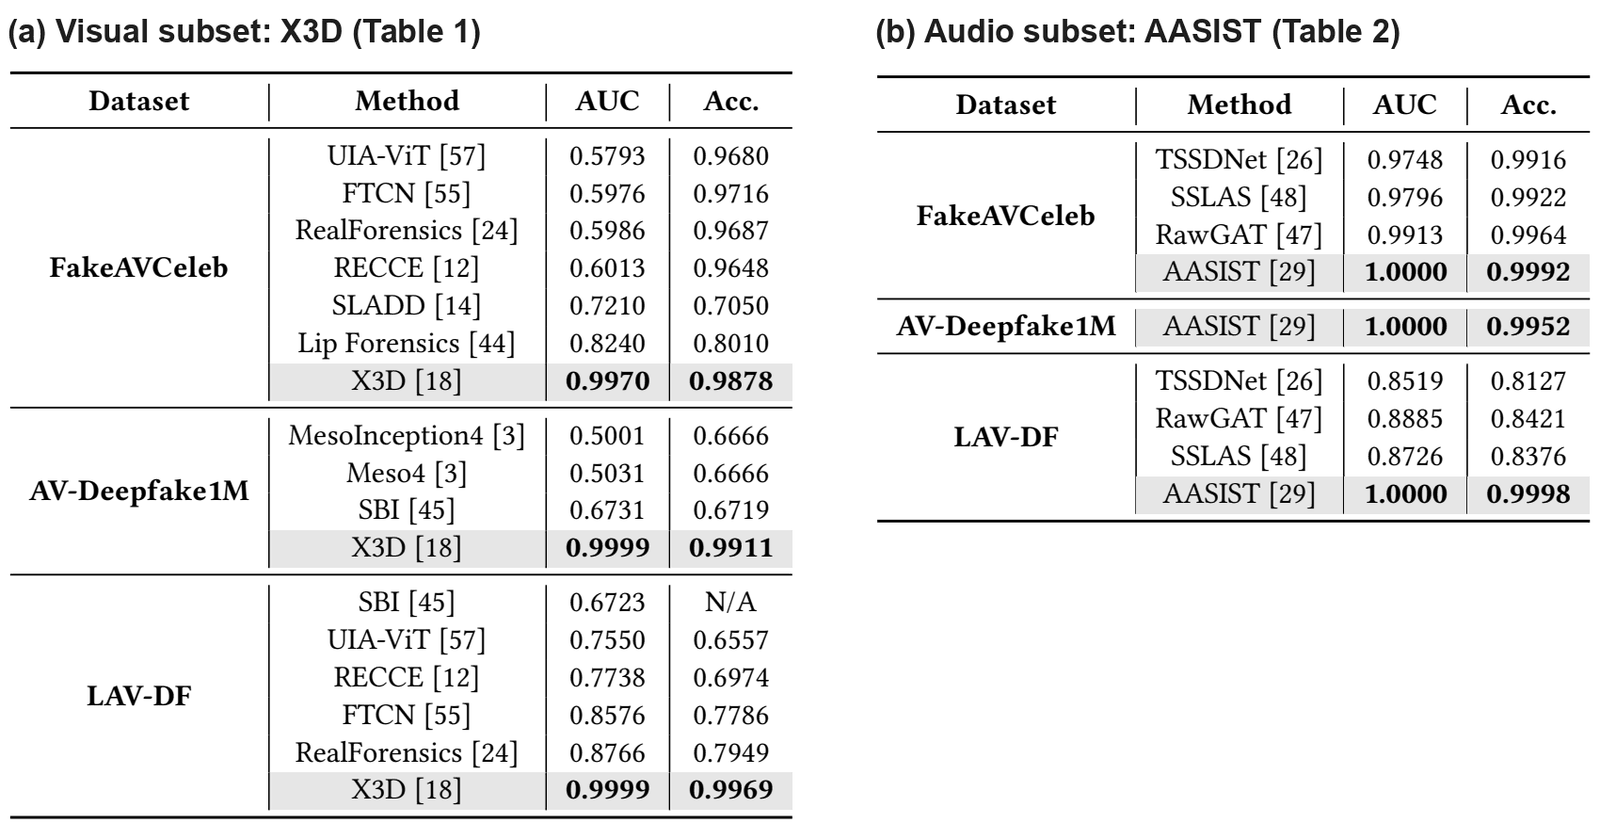
Table 3. Multimodal detection performance (AUC / accuracy)표 3. 멀티모달 탐지 성능 (AUC / 정확도)表 3. 多模态检测性能(AUC / 准确率)
| Dataset데이터셋数据集 | Method방법方法 | AUC | Acc. |
|---|---|---|---|
| FakeAVCeleb | |||
| Multimodaltrace (Multilabel) | N/A | 0.9290 | |
| BA-TFD | 0.5431 | 0.9696 | |
| RealForensics + RawGAT | 0.7919 | 0.9349 | |
| FTCN + RawGAT | 0.8063 | 0.9421 | |
| MIS-AVoiDD | 0.9730 | 0.9620 | |
| MMMS-BA | 0.9890 | 0.9790 | |
| FMDC | 0.9994 | 0.9984 | |
| X3A (ours)(제안)(本文) | 0.9968 | 0.9890 | |
| AV-Deepfake1M | |||
| MDS | 0.5657 | 0.5944 | |
| MMTFD | N/A | 0.9329 | |
| MMMS-BA | 0.9790 | 0.9680 | |
| X3A (ours)(제안)(本文) | 0.9999 | 0.9960 | |
| LAV-DF | |||
| BA-TFD | 0.5097 | 0.6529 | |
| FTCN + RawGAT | 0.8726 | 0.7063 | |
| RealForensics + RawGAT | 0.8868 | 0.7197 | |
| MMTFD | N/A | 0.9693 | |
| FMDC | 0.9998 | 0.9981 | |
| X3A (ours)(제안)(本文) | 0.9999 | 0.9976 | |
Values as reported in the paper (Table 3); bold = best per dataset, as marked in the paper. Baseline numbers come from prior literature, while X3A uses the paper's unseen-speaker test splits, so evaluation setups can differ.값은 논문 표 3 그대로이며, 굵게는 논문 표기대로 데이터셋별 1위입니다. 기준 모델 수치는 기존 문헌에서 가져왔고 X3A는 처음 보는 화자 테스트셋에서 평가했으므로, 평가 설정이 다를 수 있습니다.数值取自论文表 3;粗体为论文标注的各数据集最佳。基线数值来自已有文献,而 X3A 在论文的未见说话人测试集上评估,因此评估设置可能不同。
BibTeX
@inproceedings{park2025x3a,
  title     = {X3A: Efficient Multimodal Deepfake Detection with Score-Level Fusion},
  author    = {Park, Chan and Moon, Bohyun and Jeon, Minsun and Jung, Jee-weon
               and Woo, Simon S.},
  booktitle = {Proceedings of the 40th ACM/SIGAPP Symposium on Applied
               Computing (SAC '25)},
  year      = {2025},
  publisher = {Association for Computing Machinery},
  location  = {Catania, Italy},
  doi       = {10.1145/3672608.3707934}
}