Beyond Masking: Landmark-based Representation Learning and Knowledge-Distillation for Audio-Visual Deepfake Detection
- Audio-visual deepfake detectors often watch the background, not the face, and fail on real social-media deepfakes.
- Beyond Masking distills facial-landmark geometry into both video and audio encoders, and aligns the two over time.
- Cross-dataset: 78.12% on DFDC and 75.12% on 500+ web deepfakes, highest among compared methods, with 32.4 M parameters.
- 오디오-비주얼 딥페이크 탐지기는 얼굴보다 배경을 보는 경우가 많아, 소셜 미디어의 실제 딥페이크에서 실패합니다.
- Beyond Masking은 얼굴 랜드마크 기하 정보를 비디오·오디오 인코더 모두에 증류하고, 두 모달리티를 시간 축에서 정렬합니다.
- 교차 데이터셋: DFDC 78.12%, 웹 딥페이크 500여 개 75.12%로 비교 방법 중 최고이며, 파라미터는 32.4 M입니다.
- 音视频深度伪造检测器常常关注背景而非人脸,面对社交媒体上的真实深度伪造时失效。
- Beyond Masking 将人脸关键点几何信息蒸馏到视频和音频编码器中,并在时间上对齐两种模态。
- 跨数据集:DFDC 78.12%,500 多个网络深度伪造视频 75.12%,在对比方法中最高;参数量 32.4 M。
SSituation
- Audio-visual deepfakes fake the face, the voice, or both. They spread on social media, including political propaganda.
- Detectors trained on academic datasets (DFDC, FakeAVCeleb, KoDF) score well. On real-world deepfakes they degrade sharply, with many false alarms.
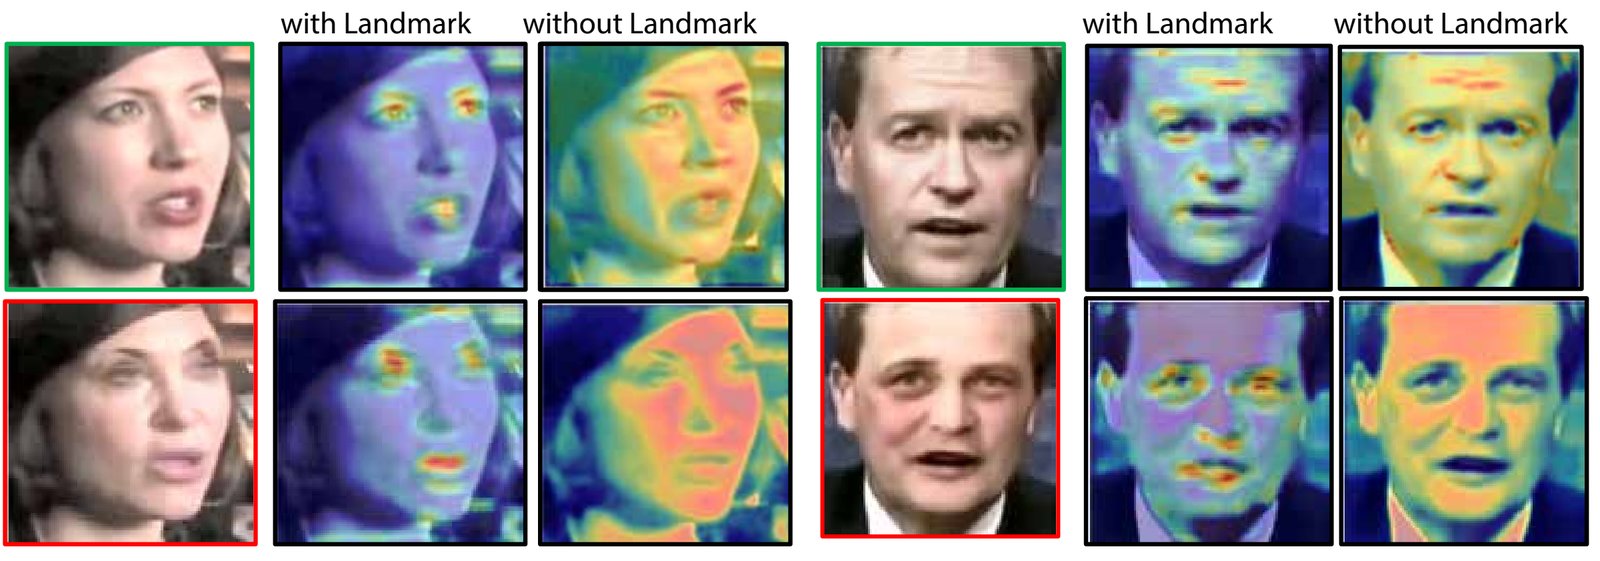
- One reason is where models look. Grad-CAM shows a standard backbone attending to background, hair and neck.
- These are spurious, dataset-specific cues. Manipulation actually happens on the face and mouth.
S상황
- 오디오-비주얼 딥페이크는 얼굴, 목소리, 또는 둘 다를 조작합니다. 정치 선전을 포함해 소셜 미디어에 퍼지고 있습니다.
- 학술 데이터셋(DFDC, FakeAVCeleb, KoDF)으로 학습한 탐지기는 수치가 높습니다. 그러나 실제 딥페이크에서는 성능이 크게 떨어지고 오탐이 많습니다.
- 원인 중 하나는 모델이 어디를 보느냐입니다. Grad-CAM으로 보면 일반 백본은 배경·머리카락·목에 주의를 둡니다.
- 이는 특정 데이터셋에 묶인 부수적 단서입니다. 실제 조작은 얼굴과 입에서 일어납니다.
S情境
- 音视频深度伪造会伪造人脸、声音或两者,正在社交媒体上传播,包括政治宣传。
- 在学术数据集(DFDC、FakeAVCeleb、KoDF)上训练的检测器分数很高,但面对真实深度伪造时性能骤降,误报很多。
- 原因之一是模型看哪里。Grad-CAM 显示,常规骨干网络把注意力放在背景、头发和脖子上。
- 这些是与特定数据集绑定的虚假线索,而篡改实际发生在人脸和嘴部。
TTask
- Make both video and audio encoders attend to facial geometry (eyes, lips, face shape), not the background.
- Check that mouth motion and speech stay synchronized over time.
- Generalize to unseen datasets and real web deepfakes with a small model.
T과제
- 비디오·오디오 인코더가 배경 대신 얼굴 기하 구조(눈, 입술, 얼굴 형태)에 집중하게 한다.
- 입 모양과 음성이 시간적으로 맞물리는지 확인한다.
- 작은 모델로 처음 보는 데이터셋과 실제 웹 딥페이크에 일반화한다.
T任务
- 让视频和音频编码器关注人脸几何结构(眼睛、嘴唇、脸型),而不是背景。
- 检查嘴部动作与语音是否在时间上同步。
- 用小模型泛化到未见过的数据集和真实网络深度伪造。
AAction
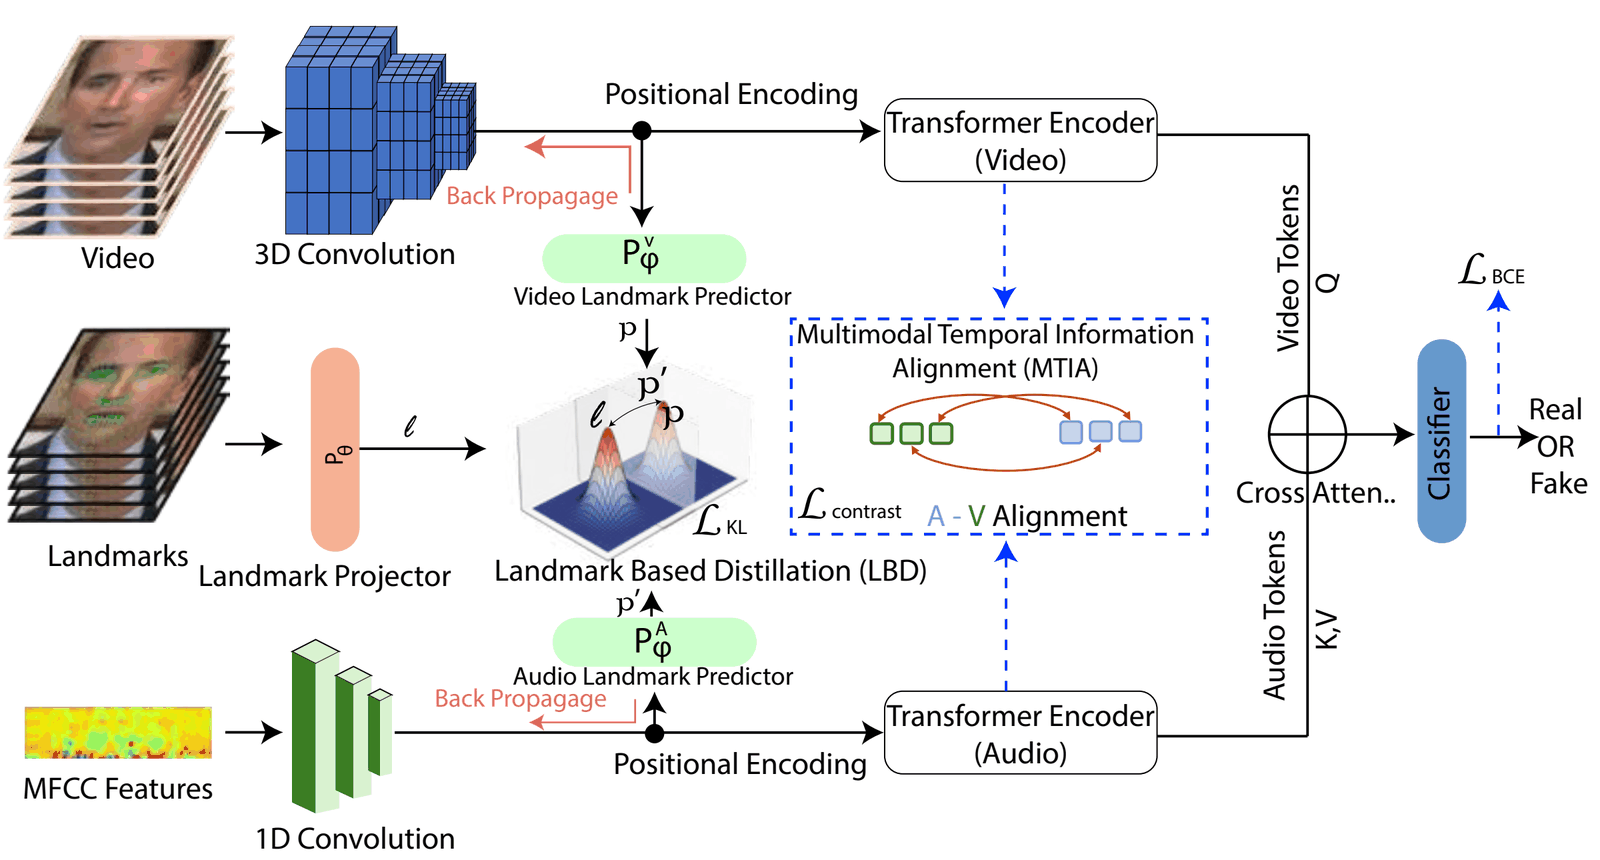
1. Landmark-based Distillation (LBD): landmarks as a teacher, not a mask.
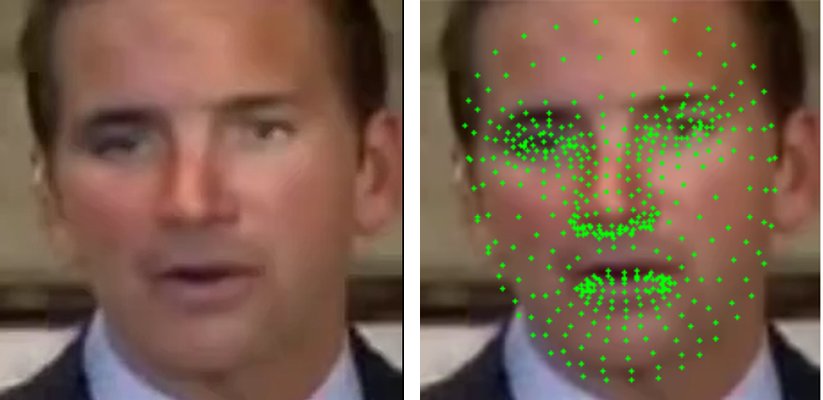
- Instead of masking the input, we extract 478 facial landmarks per frame with MediaPipe.
- A small landmark projector turns them into a target representation.
- Video and audio landmark predictors learn to reproduce it from encoder features, with a KL-divergence loss (motivated by I-JEPA).
- To reconstruct facial geometry, the encoders must look at the face. The audio encoder must infer mouth shape from sound.
A행동
1. Landmark-based Distillation (LBD): 마스크가 아니라 교사로서의 랜드마크.
- 입력을 가리는 대신, MediaPipe로 프레임마다 얼굴 랜드마크 478개를 추출합니다.
- 작은 랜드마크 프로젝터가 이를 목표 표현으로 바꿉니다.
- 비디오·오디오 랜드마크 예측기는 인코더 특징으로 이 표현을 재현하도록 KL 발산 손실로 학습합니다(I-JEPA에서 착안).
- 얼굴 기하를 재구성하려면 인코더가 얼굴을 봐야 합니다. 오디오 인코더는 소리로 입 모양을 추론해야 합니다.
A行动
1. Landmark-based Distillation(LBD):把关键点当作教师,而不是掩码。
- 不遮挡输入,而是用 MediaPipe 每帧提取 478 个人脸关键点。
- 一个小型关键点投影器将其转换为目标表示。
- 视频和音频关键点预测器以 KL 散度损失,从编码器特征中重建该表示(受 I-JEPA 启发)。
- 要重建人脸几何,编码器必须看人脸;音频编码器则必须从声音推断嘴型。
2. Multimodal Temporal Information Alignment (MTIA).
- Video and audio features pass through transformer encoders with positional encoding.
- Cross-attention (video = query, audio = key and value) feeds the real/fake classifier.
- A contrastive loss pulls matching audio-video pairs together and pushes mismatched pairs apart.
3. A real-world test set.
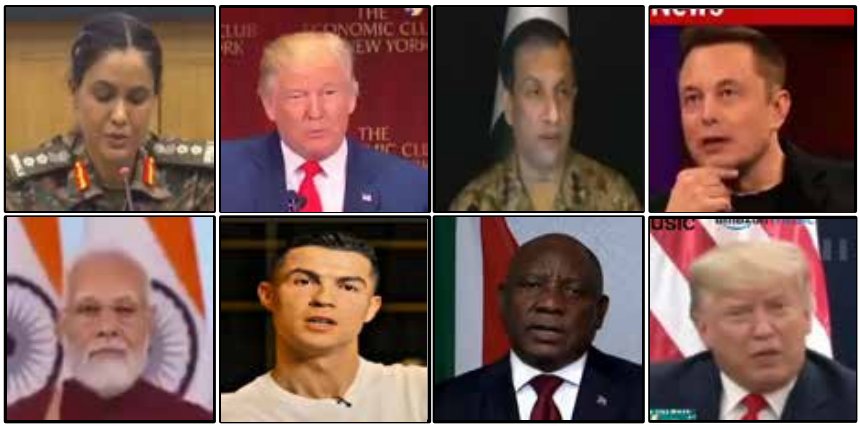
- Over 500 viral audio-visual deepfakes from major social media, chosen for video quality and audio realism.
- Includes high-profile figures such as presidents and military personnel. Paired with 500 real VoxCeleb videos.
2. Multimodal Temporal Information Alignment (MTIA).
- 비디오·오디오 특징은 위치 인코딩을 더한 트랜스포머 인코더를 거칩니다.
- 교차 어텐션(비디오 = 쿼리, 오디오 = 키·값)이 진짜/가짜 분류기로 이어집니다.
- 대조 손실은 짝이 맞는 오디오-비디오 쌍을 가깝게, 맞지 않는 쌍을 멀게 만듭니다.
3. 실제 환경 평가셋.
- 주요 소셜 미디어에서 화제가 된 오디오-비주얼 딥페이크 500여 개를 영상 품질과 음성 사실감 기준으로 수집했습니다.
- 대통령, 군 관계자 등 주요 인물이 포함됩니다. 실제 영상으로 VoxCeleb 500개를 짝지었습니다.
2. Multimodal Temporal Information Alignment(MTIA)。
- 视频与音频特征经过带位置编码的 Transformer 编码器。
- 交叉注意力(视频为 query,音频为 key 和 value)连接真伪分类器。
- 对比损失拉近匹配的音视频对,推远不匹配的对。
3. 真实场景测试集。
- 从主流社交媒体收集 500 多个热门音视频深度伪造,按视频质量和音频真实感筛选。
- 包含总统、军方人员等知名人物,并配对 500 个真实 VoxCeleb 视频。
RResult
- Generalization: trained on FakeAVCeleb + KoDF, it reaches 78.12% ACC / 78.82 AUC on unseen DFDC and 75.12% / 75.65 on the real-world web set.
- Both are the highest among methods compared in Table 2 (next best: 74.65 / 75.18 on DFDC, 68.15 / 67.87 on the web set).
- Intra-dataset: 92.38% ACC / 93.25 AUC on FakeAVCeleb, where both modalities can be faked; next best is 83.42% ACC. Best ACC on both DF-TIMIT splits.
- Efficiency: 32.4 M parameters, fewer than every multimodal baseline with a reported size (42.7–47.4 M).
- Every component helps: FakeAVCeleb accuracy rises from 72.12% (no landmarks, no MTIA) to 92.38% (Table 3). Grad-CAM attention moves from the background to the eyes and mouth.
- CIKM 2025 short paper (first author), with code released.
R결과
- 일반화: FakeAVCeleb + KoDF로 학습해 처음 보는 DFDC에서 ACC 78.12% / AUC 78.82, 실제 웹 평가셋에서 75.12% / 75.65를 기록했습니다.
- 둘 다 표 2의 비교 방법 중 최고입니다(차순위: DFDC 74.65 / 75.18, 웹 평가셋 68.15 / 67.87).
- 데이터셋 내부: 두 모달리티 모두 조작될 수 있는 FakeAVCeleb에서 ACC 92.38% / AUC 93.25이며, 차순위는 ACC 83.42%입니다. DF-TIMIT 두 분할 모두 ACC 1위입니다.
- 효율성: 파라미터 32.4 M으로, 크기가 보고된 모든 멀티모달 기준 모델(42.7–47.4 M)보다 적습니다.
- 모든 구성 요소가 기여: FakeAVCeleb 정확도가 72.12%(랜드마크·MTIA 없음)에서 92.38%로 올랐습니다(표 3). Grad-CAM 주의도 배경에서 눈과 입으로 옮겨 갔습니다.
- CIKM 2025 숏페이퍼(제1저자), 코드 공개.
R结果
- 泛化:在 FakeAVCeleb + KoDF 上训练,未见过的 DFDC 上 ACC 78.12% / AUC 78.82,真实网络测试集上 75.12% / 75.65。
- 两者均为表 2 对比方法中最高(次佳:DFDC 74.65 / 75.18,网络测试集 68.15 / 67.87)。
- 数据集内:在两种模态都可能被篡改的 FakeAVCeleb 上 ACC 92.38% / AUC 93.25,次佳方法 ACC 为 83.42%;在 DF-TIMIT 两个划分上 ACC 均为第一。
- 效率:参数量 32.4 M,少于所有报告了规模的多模态基线(42.7–47.4 M)。
- 每个组件都有贡献:FakeAVCeleb 准确率从 72.12%(无关键点、无 MTIA)提升到 92.38%(表 3);Grad-CAM 注意力从背景转向眼睛和嘴部。
- CIKM 2025 短论文(第一作者),代码已开源。
Table 2. Cross-dataset evaluation (trained on FakeAVCeleb + KoDF), ACC / AUC (%)표 2. 교차 데이터셋 평가 (FakeAVCeleb + KoDF로 학습), ACC / AUC (%)表 2. 跨数据集评估(在 FakeAVCeleb + KoDF 上训练),ACC / AUC(%)
| Methods방법方法 | Params파라미터参数量 | DFDC | RW (web)(웹)(网络) | ||
|---|---|---|---|---|---|
| ACC | AUC | ACC | AUC | ||
| Visual unimodal시각 단일 모달视觉单模态 | |||||
| SPSL (Xception) | 45.7 M | 72.62 | 73.58 | 61.28 | 61.93 |
| PRRNet | 62.1 M | 74.65 | 75.18 | 65.85 | 65.43 |
| LipForensics | 36.0 M | 71.26 | 74.30 | 63.37 | 63.82 |
| STIL | 32.5 M | 70.29 | 71.34 | 65.48 | 65.18 |
| FTCN | 26.6 M | 73.18 | 74.03 | 64.19 | 64.80 |
| Multimodal멀티모달多模态 | |||||
| Emotions | 42.7 M | 69.14 | 71.44 | 67.28 | 67.72 |
| MDS | 47.4 M | 70.29 | 70.30 | 66.84 | 67.32 |
| Joint Audio-Visual | 46.1 M | 71.22 | 72.69 | 68.15 | 67.87 |
| Ours제안 방법本文方法 | 32.4 M | 78.12 | 78.82 | 75.12 | 75.65 |
Table 1. Intra-dataset evaluation (80% / 20% split per benchmark), ACC / AUC (%)표 1. 데이터셋 내부 평가 (벤치마크별 80% / 20% 분할), ACC / AUC (%)表 1. 数据集内评估(每个基准按 80% / 20% 划分),ACC / AUC(%)
| Methods방법方法 | Params파라미터参数量 | DF-TIMIT (LQ) | DF-TIMIT (HQ) | DFDC | FakeAVCeleb | KoDF | |||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| ACC | AUC | ACC | AUC | ACC | AUC | ACC | AUC | ACC | AUC | ||
| Visual unimodal시각 단일 모달视觉单模态 | |||||||||||
| SPSL (Xception) | 45.7 M | 91.17 | 90.03 | 92.29 | 91.78 | 92.04 | 94.74 | 77.94 | 79.83 | 92.36 | 93.19 |
| PRRNet | 62.1 M | 93.86 | 95.30 | 98.72 | 98.97 | 95.24 | 96.37 | 78.17 | 79.54 | 94.52 | 94.83 |
| LipForensics | 36.0 M | 92.77 | 93.06 | 97.74 | 96.51 | 82.47 | 65.06 | 76.22 | 78.43 | 93.16 | 93.72 |
| STIL | 32.5 M | 95.76 | 94.18 | 98.24 | 99.03 | 92.17 | 95.07 | 79.80 | 78.29 | 94.14 | 93.92 |
| FTCN | 26.6 M | 93.64 | 94.41 | 96.62 | 95.39 | 94.92 | 97.88 | 78.98 | 79.21 | 93.22 | 92.96 |
| Multimodal멀티모달多模态 | |||||||||||
| DST-Net | – | – | – | – | – | 82.80 | 86.20 | 78.40 | 80.40 | – | – |
| VFD | – | – | – | – | – | 80.90 | 85.10 | 81.50 | 86.10 | – | – |
| Emotions | 42.7 M | 92.76 | 92.95 | 94.69 | 95.42 | 82.36 | 85.00 | 83.42 | 84.81 | 93.26 | 94.41 |
| MDS | 47.4 M | 93.14 | 93.14 | 94.77 | 95.02 | 82.36 | 84.47 | 81.53 | 83.24 | 93.26 | 94.41 |
| Joint Audio-Visual | 46.1 M | 75.22 | 75.69 | 81.65 | 83.47 | 90.44 | 89.94 | 81.20 | 82.45 | 92.96 | 93.59 |
| Ours제안 방법本文方法 | 32.4 M | 96.82 | 97.35 | 98.98 | 97.72 | 89.75 | 90.07 | 92.38 | 93.25 | 93.48 | 94.75 |
Values as reported in the paper (Tables 1–2). Bold = best, underline = second best; fewest parameters counts as best. For DF-TIMIT (HQ) AUC, the second-best value is PRRNet's 98.97.값은 논문 표 1–2 그대로입니다. 굵게 = 1위, 밑줄 = 2위(파라미터는 적을수록 1위). DF-TIMIT (HQ) AUC의 2위는 PRRNet의 98.97입니다.数值取自论文表 1–2。粗体 = 最佳,下划线 = 次佳(参数量越少越好)。DF-TIMIT (HQ) AUC 的次佳为 PRRNet 的 98.97。
Table 3. Ablation of LBD components and MTIA (FakeAVCeleb, %)표 3. LBD 구성 요소와 MTIA 제거 실험 (FakeAVCeleb, %)表 3. LBD 组件与 MTIA 消融实验(FakeAVCeleb,%)
| Pvφ | Paφ | Pθ | MTIA | ACC | AUC |
|---|---|---|---|---|---|
| ✗ | ✗ | ✗ | ✗ | 72.12 | 71.81 |
| ✓ | ✗ | ✓ | ✗ | 82.08 | 81.57 |
| ✗ | ✓ | ✓ | ✗ | 75.89 | 75.14 |
| ✓ | ✓ | ✗ | ✗ | 84.25 | 85.60 |
| ✓ | ✓ | ✓ | ✗ | 89.43 | 90.15 |
| ✓ | ✓ | ✓ | ✓ | 92.38 | 93.25 |
Row 1 encodes each modality separately and concatenates the features. The visual landmark predictor helps more than the audio one (rows 2–3). Combining both, adding the projector, then MTIA each add accuracy.1행은 모달리티별로 따로 인코딩해 특징을 이어 붙인 기준 모델입니다. 비디오 랜드마크 예측기가 오디오 쪽보다 효과가 큽니다(2–3행). 두 예측기 결합, 프로젝터 추가, MTIA 추가가 각각 정확도를 높입니다.第 1 行分别编码各模态并拼接特征。视频关键点预测器的作用大于音频预测器(第 2–3 行);结合两者、加入投影器、再加入 MTIA,每一步都提升准确率。
BibTeX
@inproceedings{park2025beyondmasking,
  title     = {Beyond Masking: Landmark-based Representation Learning and
               Knowledge-Distillation for Audio-Visual Deepfake Detection},
  author    = {Park, Chan and Muneer, Muhammad Shahid and Woo, Simon S.},
  booktitle = {Proceedings of the 34th ACM International Conference on
               Information and Knowledge Management (CIKM '25)},
  year      = {2025},
  publisher = {Association for Computing Machinery},
  address   = {New York, NY, USA},
  location  = {Seoul, Republic of Korea},
  doi       = {10.1145/3746252.3760853}
}