ICR-Net: Robust Deepfake Detection under Temporal Corruption
- Live streams add packet loss, bit errors and heavy compression; these temporal corruptions break existing deepfake detectors.
- We built DF-TCB (8 streaming corruptions × 3 severities) and ICR-Net, which corrects only unreliable frames.
- On FF++, ICR-Net keeps 97.9% clean accuracy and at least 92.9% under each of the 8 corruptions.
- 실시간 스트리밍의 패킷 손실, 비트 오류, 강한 압축 같은 시간적 손상은 기존 딥페이크 탐지기를 무너뜨립니다.
- DF-TCB(스트리밍 손상 8종 × 강도 3단계)와, 신뢰도가 낮은 프레임만 보정하는 ICR-Net을 만들었습니다.
- ICR-Net은 FF++에서 손상 없는 영상 97.9%, 손상 8종 각각에서 92.9% 이상의 정확도를 유지합니다.
- 直播中的丢包、比特错误和强压缩等时序损坏,会让现有深度伪造检测器失效。
- 我们构建了 DF-TCB(8 种流媒体损坏 × 3 个严重程度)和只校正不可靠帧的 ICR-Net。
- 在 FF++ 上,ICR-Net 无损坏准确率为 97.9%,8 种损坏下均不低于 92.9%。
SSituation
Deepfakes increasingly reach people through live streams and video calls.
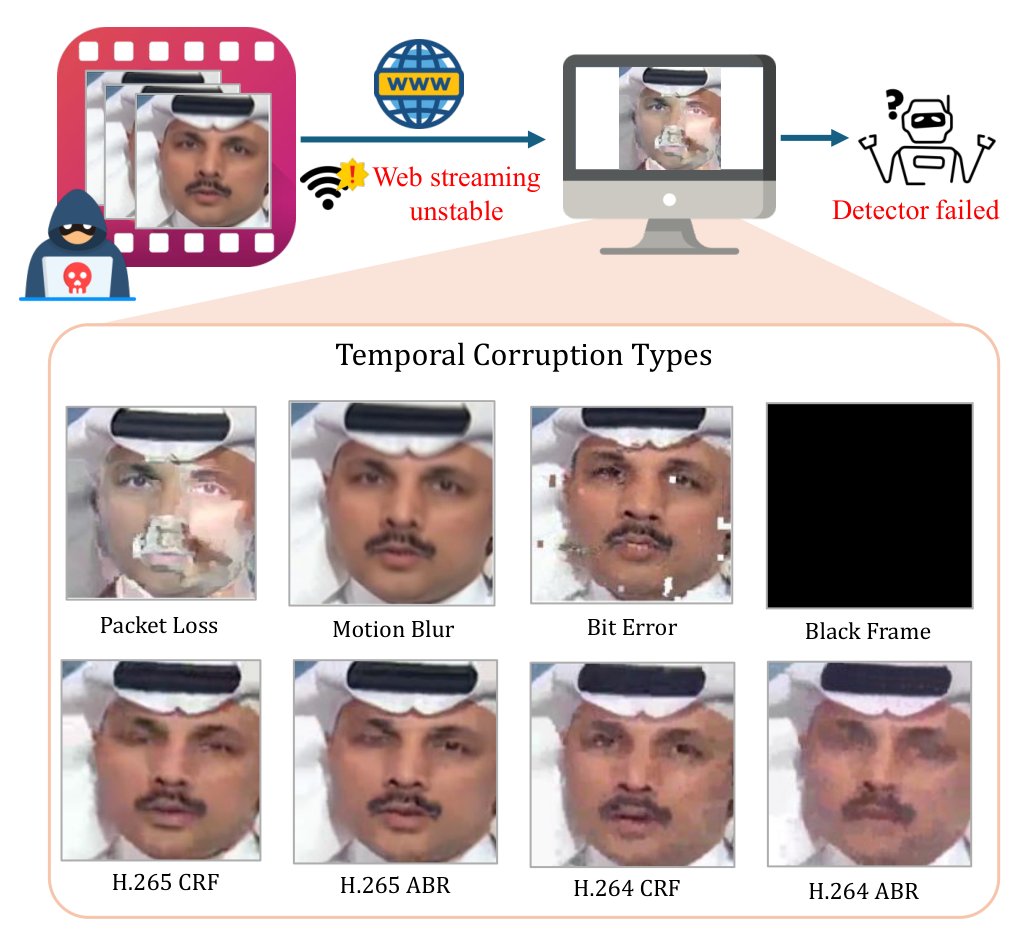
- Unstable networks corrupt video over time: dropped packets, flipped bits, black frames, heavy compression.
- Detectors had been tested on spatial corruptions (noise, blur), not on these streaming failures.
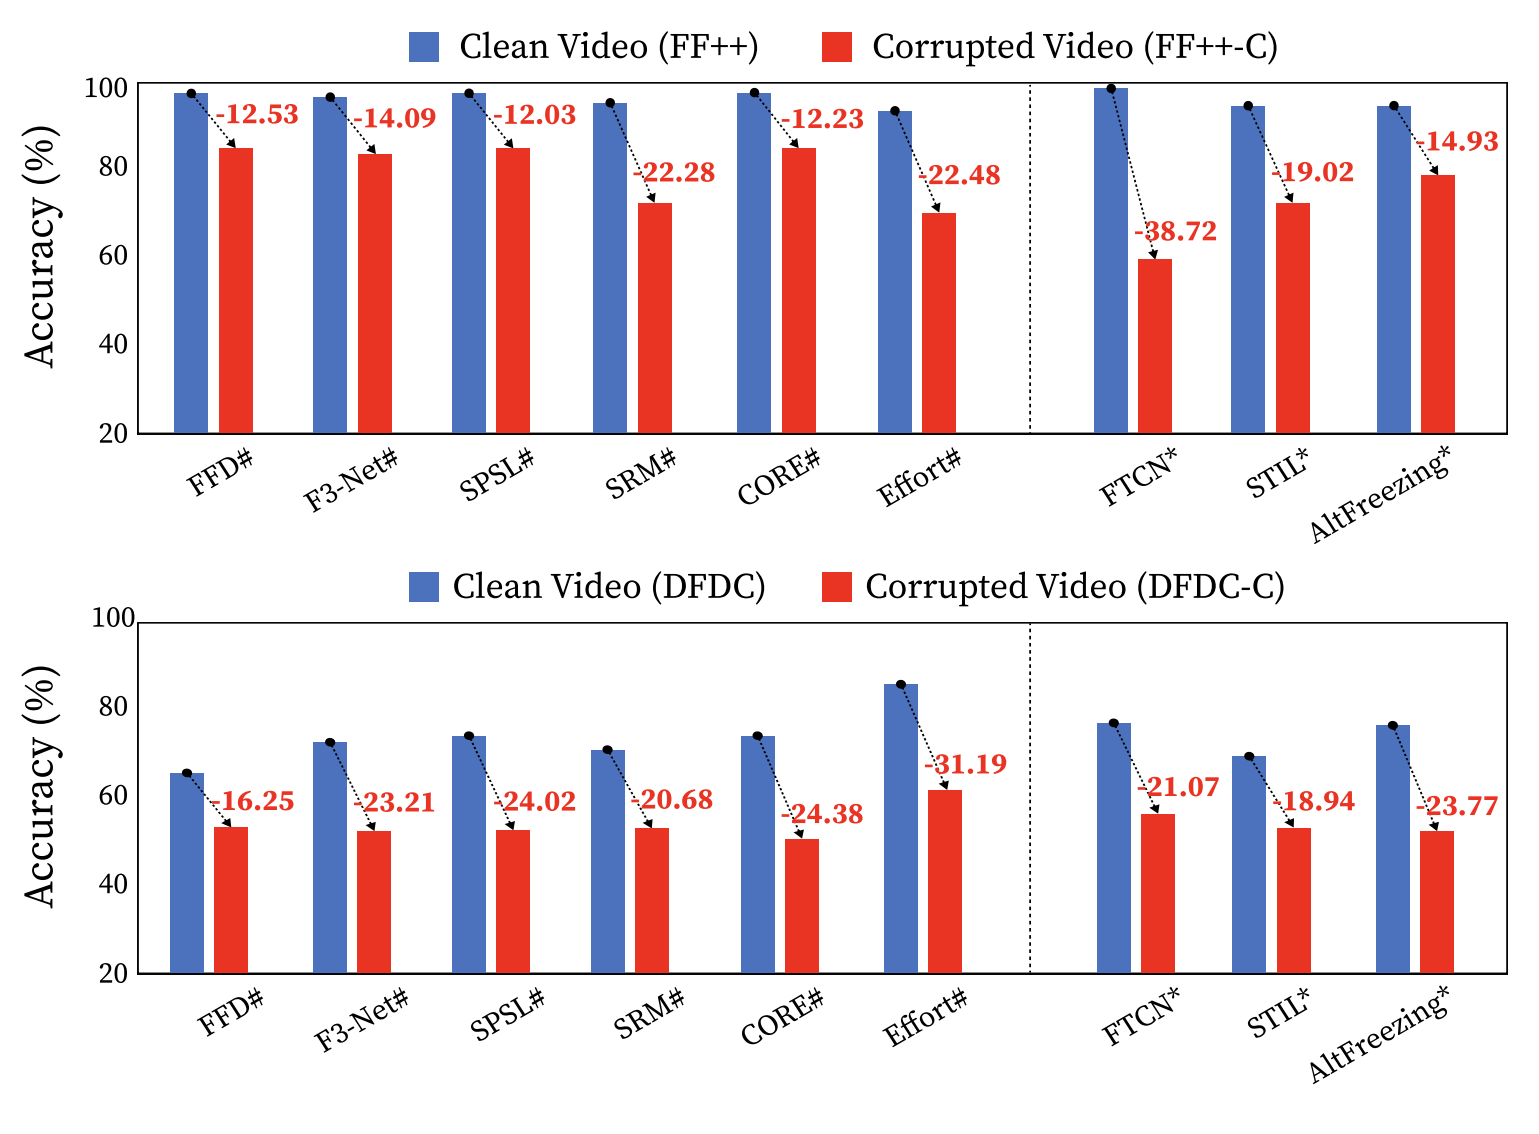
- We measured it: the video-based detector FTCN, trained on clean FaceForensics++ (FF++), dropped 38.72% from 99.65% clean accuracy.
- On corrupted DFDC, all 9 detectors dropped sharply, most to near chance level.
S상황
딥페이크는 점점 더 실시간 스트리밍과 영상 통화로 전달됩니다.
- 불안정한 네트워크는 영상을 시간 축으로 망가뜨립니다. 패킷 손실, 비트 반전, 검은 프레임, 강한 압축이 생깁니다.
- 기존 탐지기는 노이즈·블러 같은 공간적 손상으로만 검증되었고, 이런 스트리밍 장애는 다루지 않았습니다.
- 직접 측정해 보니, 깨끗한 FaceForensics++(FF++)로 학습한 비디오 기반 탐지기 FTCN은 정확도 99.65%에서 38.72% 하락했습니다.
- 손상된 DFDC에서는 9개 탐지기 모두 크게 떨어졌고, 대부분 우연 수준에 가까워졌습니다.
S情境
深度伪造越来越多地借助直播和视频通话传播。
- 不稳定的网络会让视频在时间维度上受损:丢包、比特翻转、黑帧和强压缩。
- 现有检测器只在噪声、模糊等空间损坏下测试过,没有覆盖这类流媒体故障。
- 我们实测发现:在干净的 FaceForensics++(FF++)上训练的视频检测器 FTCN,准确率从 99.65% 下降了 38.72%。
- 在受损的 DFDC 上,9 个检测器全部大幅下降,多数接近随机水平。
TTask
- Measure: build a benchmark of realistic streaming failures on standard deepfake datasets.
- Fix: design a detector that stays accurate on partly corrupted clips, without losing clean accuracy.
T과제
- 측정: 표준 딥페이크 데이터셋 위에 실제 스트리밍 장애를 재현한 벤치마크를 만든다.
- 해결: 클립 일부가 손상되어도 정확하고, 손상 없는 영상의 정확도도 지키는 탐지기를 설계한다.
T任务
- 度量:在标准深度伪造数据集上构建模拟真实流媒体故障的基准。
- 解决:设计一个检测器,片段部分受损时仍保持准确,且不牺牲无损坏视频上的准确率。
AAction
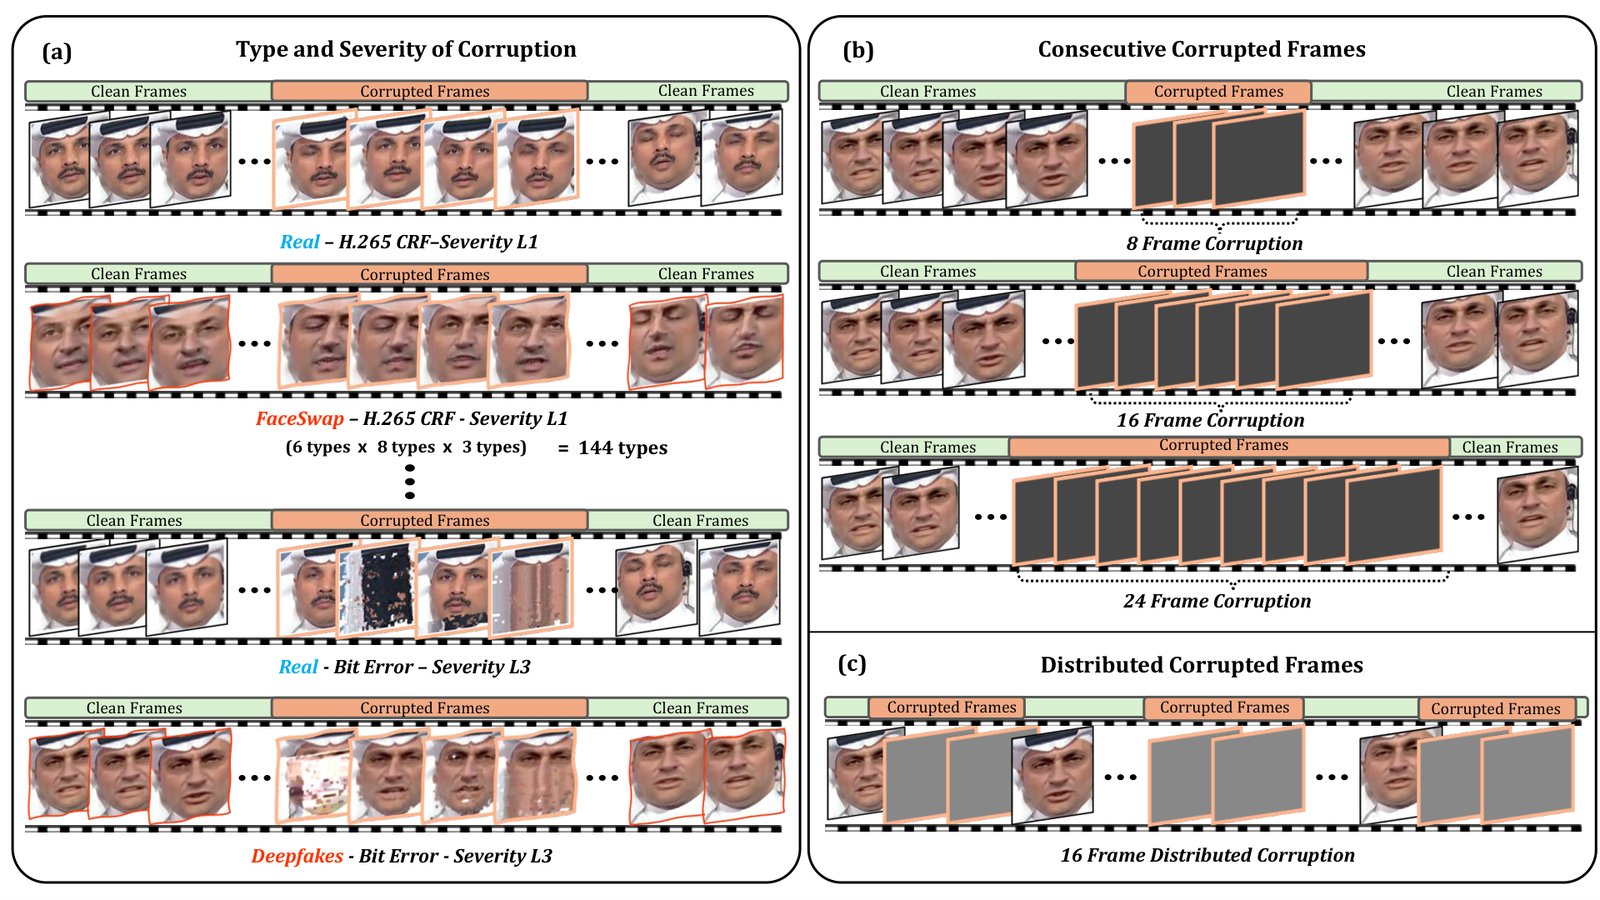
1. DF-TCB benchmark.
- I simulated 8 temporal corruptions on FF++ and DFDC, each at 3 severity levels.
- Types: black frames, motion blur, packet loss (Mininet network with UDP), bit errors, and H.264 / H.265 compression.
- Compression uses both constant-rate-factor (CRF) and average-bitrate (ABR) modes.
- By default, 16 consecutive frames of each 32-frame clip are corrupted.
- This yields the corrupted splits FF++-C (intra-dataset) and DFDC-C (cross-dataset).
A행동
1. DF-TCB 벤치마크.
- FF++와 DFDC 위에 시간적 손상 8종을 각각 강도 3단계로 시뮬레이션했습니다.
- 유형: 검은 프레임, 모션 블러, 패킷 손실(Mininet 가상 네트워크 + UDP), 비트 오류, H.264 / H.265 압축.
- 압축은 CRF와 평균 비트레이트(ABR) 두 방식을 모두 사용합니다.
- 기본 설정에서는 32프레임 클립마다 연속 16프레임을 손상시킵니다.
- 그 결과 FF++-C(데이터셋 내부)와 DFDC-C(교차 데이터셋) 손상 분할을 만들었습니다.
A行动
1. DF-TCB 基准。
- 在 FF++ 和 DFDC 上模拟 8 种时序损坏,每种 3 个严重程度。
- 类型:黑帧、运动模糊、丢包(Mininet 虚拟网络 + UDP)、比特错误,以及 H.264 / H.265 压缩。
- 压缩同时采用 CRF 和平均码率(ABR)两种模式。
- 默认每个 32 帧片段中连续 16 帧受损。
- 由此得到损坏数据划分 FF++-C(数据集内)和 DFDC-C(跨数据集)。
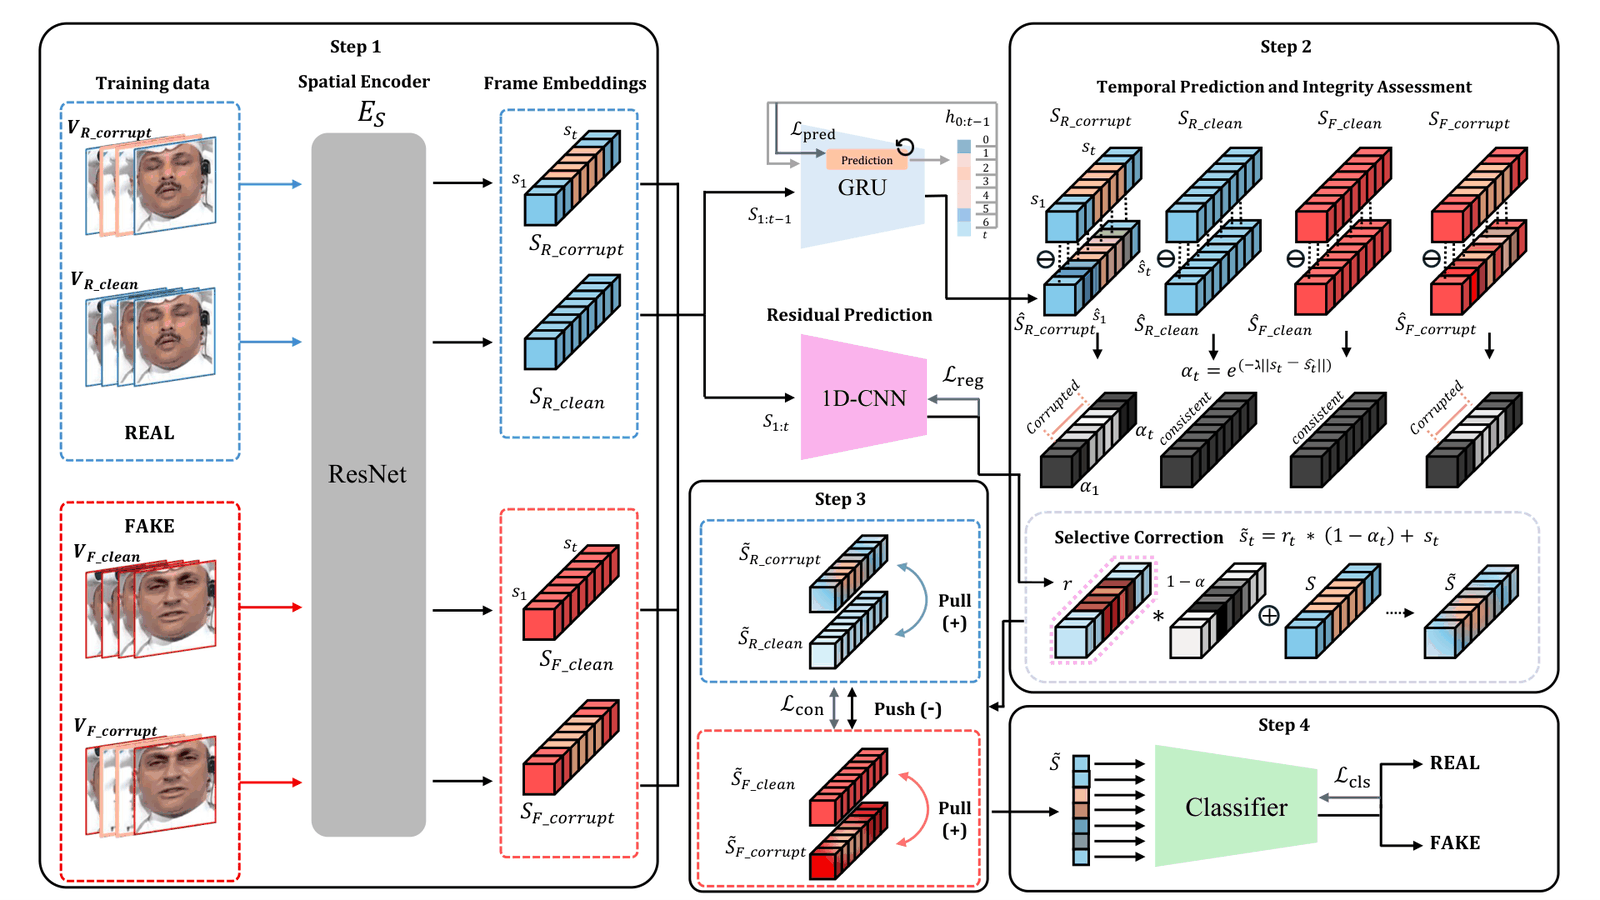
2. ICR-Net. Idea: a corrupted frame is one the model cannot predict from its neighbours. Correct only those frames; leave reliable ones untouched.
- Integrity scoring: a GRU predicts each frame embedding from the preceding frames. A large error means low integrity.
- Selective correction: a 1D-CNN branch estimates a residual correction, scaled by how unreliable the frame is. Trustworthy frames keep their forensic cues.
- Contrastive alignment: clean and corrupted views of one video are pulled together; the opposite class is pushed apart. Features become corruption-invariant yet still separate real from fake.
2. ICR-Net. 핵심 아이디어: 손상된 프레임은 주변 프레임으로 예측되지 않는 프레임입니다. 그런 프레임만 보정하고, 신뢰할 수 있는 프레임은 그대로 둡니다.
- 무결성 점수: GRU가 이전 프레임들로 현재 프레임 임베딩을 예측합니다. 오차가 크면 무결성이 낮습니다.
- 선택적 보정: 1D-CNN 브랜치가 잔차 보정값을 추정하고, 신뢰도가 낮은 프레임일수록 크게 적용합니다. 신뢰할 수 있는 프레임은 위조 단서를 유지합니다.
- 대조 정렬: 같은 영상의 깨끗한 버전과 손상 버전은 가깝게, 반대 클래스는 멀게 학습합니다. 손상에 둔감하면서도 진짜/가짜를 구분하는 특징을 얻습니다.
2. ICR-Net。核心思路:受损帧就是无法由相邻帧预测的帧。只校正这些帧,可靠帧保持不变。
- 完整性评分:GRU 根据前面的帧预测当前帧嵌入;预测误差越大,完整性越低。
- 选择性校正:1D-CNN 分支估计残差校正量,帧越不可靠,校正越强;可靠帧保留伪造线索。
- 对比对齐:拉近同一视频的干净视图与受损视图,推远相反类别,得到对损坏不敏感、仍能区分真伪的特征。
RResult
- On clean FF++, ICR-Net keeps 97.86% video-level accuracy.
- It stays at or above 92.93% under each of the 8 corruptions.
- It is the most accurate model on 7 of the 8 corruption types.
- Cross-dataset (trained on FF++, tested on corrupted DFDC): most accurate on all 8 corruption types.
- Every training objective helps: 95.67% on corrupted data vs. 86.38% for the classification-only baseline (Table 3).
- Published at PAKDD 2026 (first author). A Korean patent application on the method was filed in 2026.
R결과
- 손상 없는 FF++에서 비디오 단위 정확도 97.86%를 유지합니다.
- 손상 8종 각각에서 92.93% 이상이며, 8종 중 7종에서 비교 모델 중 가장 높습니다.
- 교차 데이터셋(FF++ 학습, 손상된 DFDC 평가)에서는 손상 8종 모두에서 가장 높습니다.
- 모든 학습 목적함수가 기여합니다. 손상 데이터에서 95.67%로, 분류 손실만 쓴 기준 모델(86.38%)보다 높습니다(표 3).
- PAKDD 2026 제1저자 논문. 이 방법으로 2026년 국내 특허를 출원했습니다.
R结果
- 在无损坏的 FF++ 上,视频级准确率为 97.86%。
- 8 种损坏下均不低于 92.93%,其中 7 种在对比模型中最高。
- 跨数据集(FF++ 训练,受损 DFDC 测试):在全部 8 种损坏上准确率最高。
- 每个训练目标都有贡献:完整模型在受损数据上达 95.67%,仅用分类损失的基线为 86.38%(表 3)。
- 发表于 PAKDD 2026(第一作者);该方法已于 2026 年提交韩国专利申请。
Table 1. Intra-dataset robustness (FF++ / FF++-C), video-level accuracy (%)표 1. 데이터셋 내부 강건성 (FF++ / FF++-C), 비디오 단위 정확도 (%)表 1. 数据集内鲁棒性(FF++ / FF++-C),视频级准确率(%)
| Model모델模型 | Clean손상 없음无损坏 | Black Frame | Motion Blur | Packet Loss | Bit Error | H.264 CRF | H.264 ABR | H.265 CRF | H.265 ABR |
|---|---|---|---|---|---|---|---|---|---|
| Frame-based프레임 기반基于帧 | |||||||||
| FFD | 98.14 | 85.89 | 91.23 | 90.98 | 90.83 | 91.80 | 88.70 | 91.44 | 90.63 |
| F3-Net | 98.10 | 85.84 | 88.16 | 90.22 | 90.47 | 90.47 | 88.33 | 89.21 | 92.05 |
| SPSL | 98.29 | 84.76 | 91.24 | 86.94 | 91.84 | 85.64 | 85.31 | 91.89 | 91.81 |
| SRM | 97.87 | 86.11 | 88.27 | 90.85 | 92.09 | 91.45 | 91.17 | 90.04 | 90.21 |
| CORE | 98.27 | 85.23 | 85.14 | 90.18 | 91.43 | 86.22 | 87.93 | 89.10 | 90.66 |
| Effort | 94.40 | 84.36 | 85.52 | 86.75 | 87.26 | 85.80 | 85.61 | 85.52 | 86.67 |
| Video-based비디오 기반基于视频 | |||||||||
| FTCN | 87.62 | 86.37 | 82.64 | 82.97 | 82.65 | 83.48 | 83.69 | 83.69 | 83.54 |
| STIL | 97.35 | 86.00 | 91.31 | 86.83 | 89.58 | 88.35 | 89.15 | 92.16 | 89.28 |
| AltFreezing | 97.21 | 91.54 | 90.71 | 85.73 | 90.77 | 89.40 | 94.58 | 92.55 | 90.47 |
| ICR-Net (ours)(제안)(本文) | 97.86 | 94.92 | 94.88 | 96.03 | 96.67 | 96.55 | 92.93 | 97.50 | 95.83 |
Table 2. Cross-dataset robustness (DFDC / DFDC-C), video-level accuracy (%)표 2. 교차 데이터셋 강건성 (DFDC / DFDC-C), 비디오 단위 정확도 (%)表 2. 跨数据集鲁棒性(DFDC / DFDC-C),视频级准确率(%)
| Model모델模型 | Clean손상 없음无损坏 | Black Frame | Motion Blur | Packet Loss | Bit Error | H.264 CRF | H.264 ABR | H.265 CRF | H.265 ABR |
|---|---|---|---|---|---|---|---|---|---|
| Frame-based프레임 기반基于帧 | |||||||||
| FFD | 61.41 | 50.32 | 50.12 | 50.49 | 50.22 | 50.38 | 50.19 | 51.02 | 49.73 |
| F3-Net | 72.02 | 49.93 | 49.77 | 50.01 | 49.92 | 50.13 | 49.68 | 49.33 | 49.59 |
| SPSL | 72.15 | 50.41 | 50.18 | 50.25 | 49.97 | 50.03 | 49.83 | 50.31 | 50.28 |
| SRM | 69.91 | 50.11 | 50.34 | 49.95 | 50.21 | 49.87 | 49.72 | 49.54 | 49.61 |
| CORE | 71.28 | 50.23 | 49.91 | 50.17 | 50.33 | 49.88 | 49.52 | 49.78 | 49.44 |
| Effort | 79.85 | 55.13 | 54.88 | 54.02 | 54.71 | 54.96 | 53.87 | 55.43 | 53.69 |
| Video-based비디오 기반基于视频 | |||||||||
| FTCN | 61.21 | 53.11 | 52.89 | 53.39 | 54.12 | 53.02 | 52.07 | 53.34 | 53.55 |
| STIL | 67.71 | 49.15 | 49.98 | 48.50 | 50.05 | 48.61 | 48.01 | 50.24 | 49.82 |
| AltFreezing | 72.95 | 51.82 | 50.73 | 51.23 | 50.15 | 51.35 | 49.22 | 57.11 | 51.47 |
| ICR-Net (ours)(제안)(本文) | 78.56 | 58.14 | 59.23 | 59.51 | 58.98 | 59.12 | 57.98 | 59.88 | 58.33 |
All models use the same corruption-aware training: each training video gives a clean clip and one clip with a corruption at severity level 3. Corrupted columns average the three severity levels. Bold = best, underline = second best, as marked in the paper.모든 모델은 동일한 손상 인지 학습을 사용합니다. 학습 영상마다 깨끗한 클립 1개와 강도 3단계 손상 클립 1개를 씁니다. 손상 열은 강도 3단계의 평균입니다. 굵게 = 1위, 밑줄 = 2위(논문 표기 그대로).所有模型采用相同的损坏感知训练:每个训练视频提供 1 个干净片段和 1 个严重程度为 3 的损坏片段。损坏列为三个严重程度的平均值。粗体 = 最佳,下划线 = 次佳(按论文标注)。
Table 3. Ablation of training objectives (accuracy, %)표 3. 학습 목적함수 제거 실험 (정확도, %)表 3. 训练目标消融实验(准确率,%)
| Lpred | Lreg | Lcon | Clean손상 없음无损坏 | Corrupted손상损坏 |
|---|---|---|---|---|
| × | × | × | 91.57 | 86.38 |
| ✓ | × | × | 96.50 | 88.38 |
| × | ✓ | × | 82.54 | 77.61 |
| × | × | ✓ | 95.31 | 85.20 |
| ✓ | ✓ | × | 97.33 | 89.96 |
| × | ✓ | ✓ | 84.33 | 78.14 |
| ✓ | × | ✓ | 96.55 | 91.15 |
| ✓ | ✓ | ✓ | 97.86 | 95.67 |
Row 1 (classification loss only) is the baseline. Lreg alone hurts accuracy, because the model can trivially minimize the integrity scores. Combined with the other terms, it gives the best result.1행(분류 손실만 사용)이 기준 모델입니다. Lreg만 쓰면 모델이 무결성 점수를 쉽게 최소화해 정확도가 떨어집니다. 다른 항과 함께 쓰면 가장 좋은 결과를 냅니다.第 1 行(仅分类损失)为基线。单独使用 Lreg 会降低准确率,因为模型可以轻易把完整性分数降到最低;与其他项结合时效果最佳。
BibTeX
@inproceedings{park2026icrnet,
  title     = {{ICR-Net}: Robust Deepfake Detection under Temporal Corruption},
  author    = {Park, Chan and Choi, Hyeongjun and Muneer, Muhammad Shahid
               and Le, Binh Minh and Woo, Simon S.},
  booktitle = {Proceedings of the 30th Pacific-Asia Conference on Knowledge
               Discovery and Data Mining (PAKDD 2026)},
  year      = {2026},
  doi       = {10.1007/978-981-92-1465-5_24}
}