Publications논문论文
Highlighted: first-author papers. * equal contribution.강조 표시: 제1저자 논문. * 동등 기여.高亮:第一作者论文。* 同等贡献。
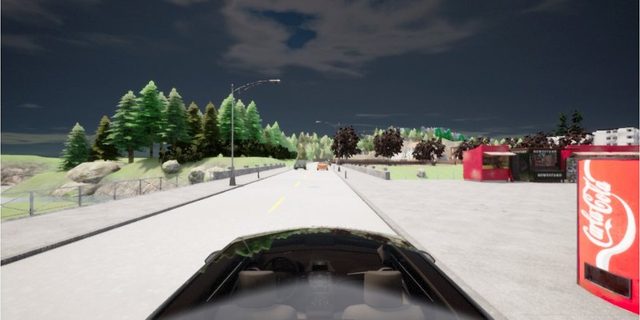
Interpretable Autonomous Driving VLA through Belief Distillation (IBD)
Ongoing project진행 중인 프로젝트进行中的项目
Ongoing project: keep a driving VLA's commentary honest and move the safety knowledge in privileged simulator labels into a camera-only belief token with a readable risk map.
진행 중인 프로젝트: 주행 VLA의 해설은 정직하게 두고, 특권 시뮬레이터 라벨의 안전 지식은 사람이 읽을 수 있는 위험 지도를 가진 카메라 기반 신념 토큰으로 옮깁니다.
进行中的项目:让驾驶 VLA 的解说保持如实,并把特权仿真标签中的安全知识转移到仅依赖相机、带可读风险地图的信念 token 中。
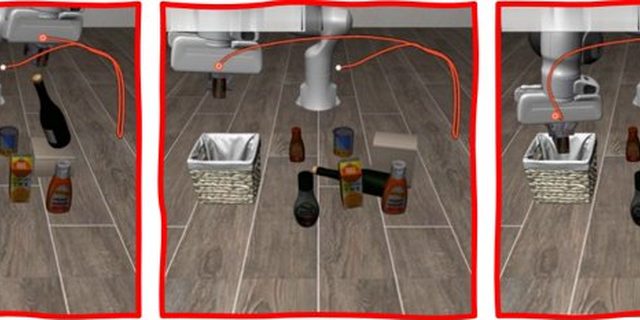
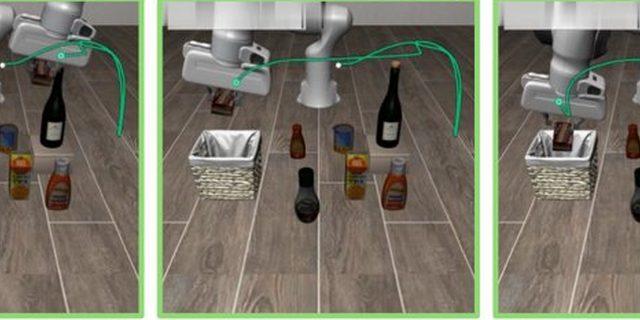
Route-Guided CBF-QP Repair for Safe Vision-Language-Action Models
RSS 2026 Workshop on Trustworthy Embodied Foundation Models
[details][상세][详情] [project page][프로젝트 페이지][项目主页] [code][코드][代码]
Post-hoc CBF-QP repair: a soft route around obstacles, with the hard safety constraint kept. SafeLIBERO collision avoidance 64.7% → 69.1% (4-suite average vs. AEGIS).
사후 CBF-QP 복구: 장애물을 돌아가는 경로를 소프트 가이던스로 더하고 안전 제약은 하드로 유지. SafeLIBERO 충돌 회피율 64.7% → 69.1% (4개 스위트 평균, AEGIS 대비).
事后 CBF-QP 修复:以软引导加入绕障路径,安全约束保持为硬约束。SafeLIBERO 避碰率 64.7% → 69.1%(4 个套件平均,对比 AEGIS)。
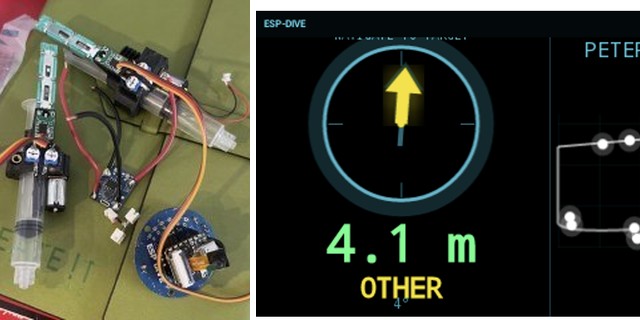
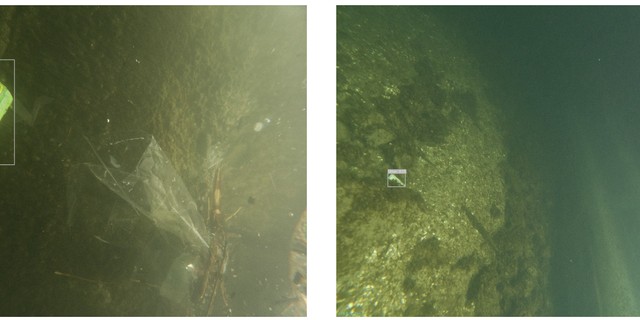
Submersivity: XR-Guided Garbage Detection with an RC Submarine for Peter Street Basin Cleanup
IEEE International Conference on Mechatronics and Automation (ICMA) 2026
[details][상세][详情] [project page][프로젝트 페이지][项目主页] [code][코드][代码]
An RC submarine streams video to a YOLOv8s debris detector; COLMAP + ArUco map the detections, and an XR goggle HUD guides the swimmer.
RC 잠수정 영상을 YOLOv8s 쓰레기 탐지 모델로 분석하고, COLMAP + ArUco로 탐지 위치를 지도에 올려 XR 고글 HUD로 안내합니다.
RC 潜艇视频经 YOLOv8s 垃圾检测器分析,COLMAP + ArUco 将检测标到地图上,再由 XR 泳镜 HUD 引导游泳者。
State-of-Flight: Wearable EEG and Motion Context During Flying or Floating
IEEE International Symposium on Computer-Based Medical Systems (CBMS) 2026
Wearable EEG and motion context captured while flying or floating (preliminary field study).
비행 또는 부유 중 웨어러블 EEG와 움직임 맥락을 기록한 예비 현장 연구입니다.
在飞行或漂浮时采集可穿戴 EEG 与运动情境数据的初步现场研究。
ICR-Net: Robust Deepfake Detection under Temporal Corruption
Pacific-Asia Conference on Knowledge Discovery and Data Mining (PAKDD) 2026
[details][상세][详情] [project page][프로젝트 페이지][项目主页] [paper][논문][论文] [code][코드][代码]
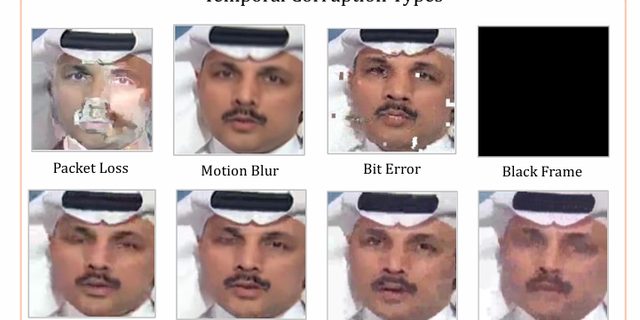
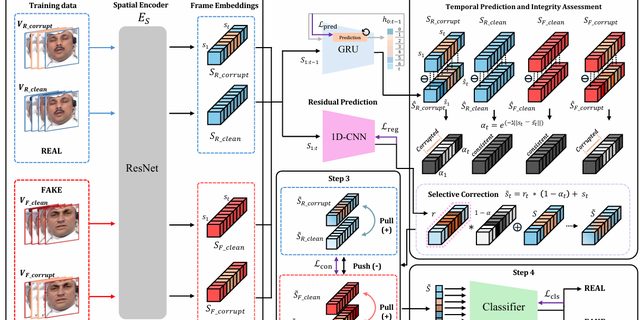
Per-frame integrity scoring and selective correction keep FF++ accuracy at or above 92.9% under each of 8 streaming corruptions (97.9% clean).
프레임별 무결성 점수와 선택적 보정으로, FF++ 스트리밍 손상 8종 각각에서 정확도 92.9% 이상 유지 (손상 없음 97.9%).
逐帧完整性评分与选择性校正:在 FF++ 上 8 种流媒体损坏下准确率均不低于 92.9%(无损坏 97.9%)。
ACM International Conference on Information and Knowledge Management (CIKM) 2025, Short Paper
[details][상세][详情] [project page][프로젝트 페이지][项目主页] [paper][논문][论文] [code][코드][代码]
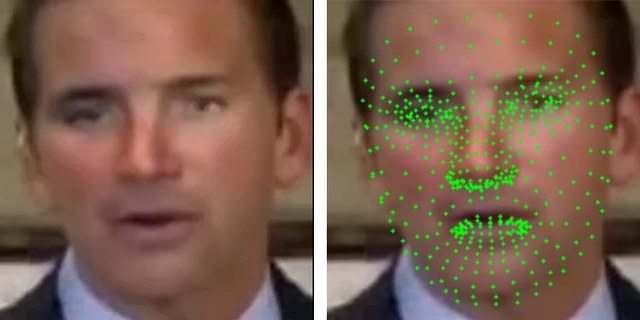
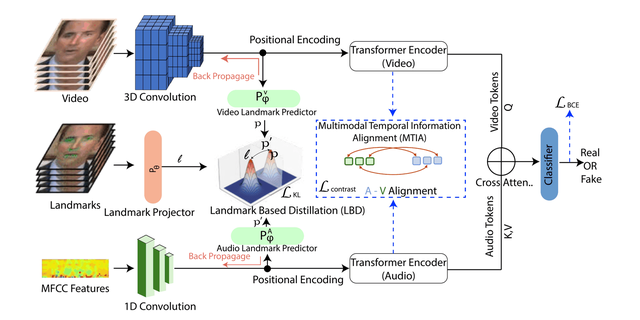
Facial-landmark distillation plus audio-visual temporal alignment; highest cross-dataset accuracy among compared methods on DFDC and 500+ web deepfakes, with 32.4 M parameters.
얼굴 랜드마크 증류 + 오디오-비주얼 시간 정렬. DFDC와 웹 딥페이크 500여 개 교차 데이터셋 평가에서 비교 방법 중 최고 정확도, 파라미터 32.4 M.
人脸关键点蒸馏 + 音视频时序对齐;在 DFDC 和 500 多个网络深度伪造视频的跨数据集测试中,准确率在对比方法中最高,参数量 32.4 M。
X3A: Efficient Multimodal Deepfake Detection with Score-Level Fusion
ACM/SIGAPP Symposium on Applied Computing (SAC) 2025
[details][상세][详情] [paper][논문][论文]
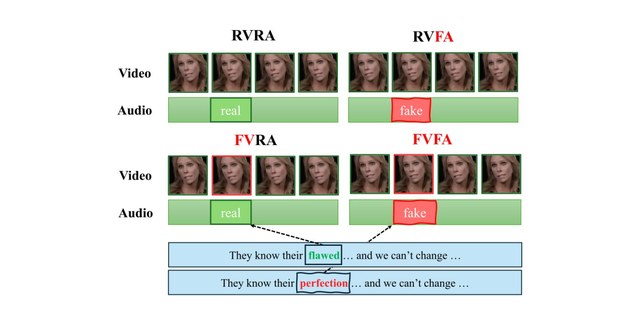
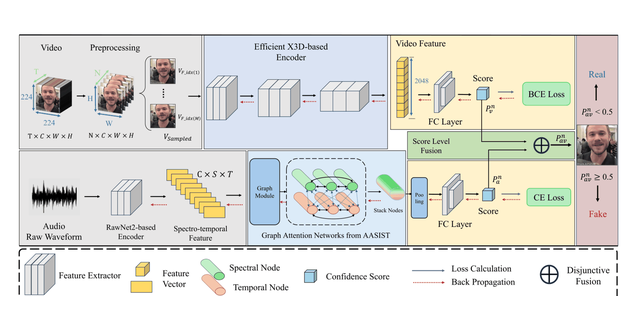
Score-level fusion of X3D (raw video) and AASIST (raw audio) for video-level deepfake detection; AUC 0.9999 / accuracy 0.9960 on AV-Deepfake1M, highest among methods compared in the paper.
X3D(원본 비디오)와 AASIST(원본 오디오)의 점수 단위 결합으로 비디오 단위 딥페이크 탐지. AV-Deepfake1M AUC 0.9999 / 정확도 0.9960, 논문의 비교 방법 중 최고.
将 X3D(原始视频)与 AASIST(原始音频)进行分数级融合,实现视频级深度伪造检测;AV-Deepfake1M 上 AUC 0.9999 / 准确率 0.9960,在论文对比方法中最高。
Weighted Contrastive Learning for Robust Audio-Visual Deepfake Detection
Under review심사 중审稿中
[details][상세][详情] [code][코드][代码]
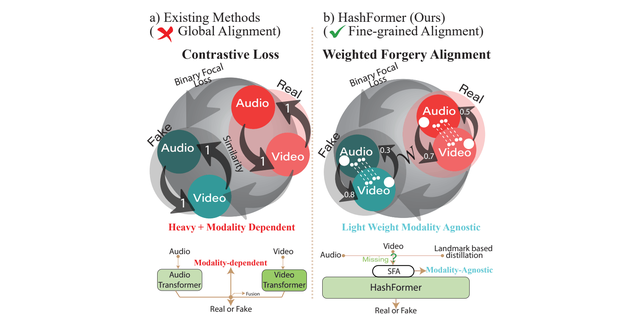
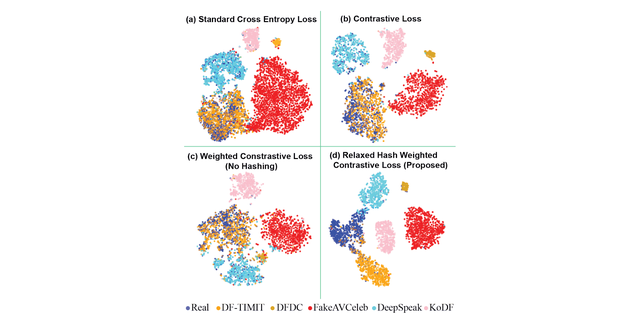
HashFormer: a lightweight audio-visual deepfake detector with a weighted contrastive-style loss in a binary hash space, designed to stay robust when a modality is missing.
HashFormer: 이진 해시 공간의 가중 대조 학습형 손실을 쓰는 경량 음성-영상 딥페이크 탐지기로, 한 모달리티가 빠져도 견고하도록 설계되었습니다.
HashFormer:在二值哈希空间中使用加权对比式损失的轻量级音视频深度伪造检测器,设计上可在缺失某一模态时保持稳健。