MetaForensic: Partial-Manipulation Deepfake Attacks (KIISE Excellence Award)
TL;DR
- The KIISE red-team track asked for deepfakes that spread a false message yet stay hard to detect.
- Team MetaForensic changed only the few words or short segments that flip the message, across 590 silent videos.
- Result: Excellence Award (우수상), Korean Institute of Information Scientists and Engineers (KIISE), Jul. 2025.
- KIISE 경진대회 레드팀 트랙은 탐지되기 어려우면서 허위 메시지를 퍼뜨리는 딥페이크를 요구했습니다.
- MetaForensic 팀은 무음 영상 590개에서 메시지를 뒤집는 몇 단어나 짧은 구간만 바꿨습니다.
- 결과: KIISE(한국정보과학회) 우수상, 2025년 7월.
- KIISE 红队赛道要求生成既能传播虚假信息、又难以被检测的深度伪造视频。
- MetaForensic 团队在 590 个无声视频中,只改动足以反转信息的少数词语或短片段。
- 结果:KIISE 优秀奖(우수상),2025年7月。
Team MetaForensic · KIISE Deepfake Generation & Detection Competition, red-team track, Jun. 2025 · Excellence Award, Jul. 2025. A team project: our team co-built the pipeline below.
SSituation
- The red-team track asked for deepfakes that spread a false message yet stay hard to detect.
- Most detectors are built for scenarios where the whole image or video is fake. They are weak on partial edits.
- Changing a few words, or the face for a moment, can still distort what a video says.
TTask
- Input: 590 source videos with no audio track.
- Goal: alter only the frames needed to change the message. Keep everything else real.
MetaForensic 팀 · KIISE 딥페이크 생성·탐지 경진대회 레드팀 트랙, 2025년 6월 · 우수상, 2025년 7월. 팀 프로젝트로, 아래 파이프라인을 팀원들과 함께 만들었습니다.
S상황
- 레드팀 트랙은 탐지되기 어려우면서 허위 메시지를 퍼뜨리는 딥페이크를 요구했습니다.
- 대부분의 탐지기는 이미지나 영상 전체가 조작된 경우를 전제로 설계되어, 부분 조작에 약합니다.
- 몇 단어나 아주 짧은 순간의 얼굴만 바꿔도 영상의 의미를 왜곡할 수 있습니다.
T과제
- 입력: 오디오 트랙이 없는 원본 영상 590개.
- 목표: 메시지를 바꾸는 데 꼭 필요한 프레임만 조작하고, 나머지는 진짜 그대로 둔다.
MetaForensic 团队 · KIISE 深度伪造生成与检测竞赛红队赛道,2025年6月 · 优秀奖,2025年7月。这是团队项目:下面的流程由我们团队共同搭建。
S情境
- 红队赛道要求生成既能传播虚假信息、又难以被检测的深度伪造视频。
- 多数检测器针对整张图像或整段视频被篡改的场景设计,对局部篡改较弱。
- 只改几个词,或在一瞬间换掉人脸,就足以扭曲视频的含义。
T任务
- 输入:590 个没有音轨的原始视频。
- 目标:只篡改改变信息所必需的帧,其余部分保持真实。
AAction
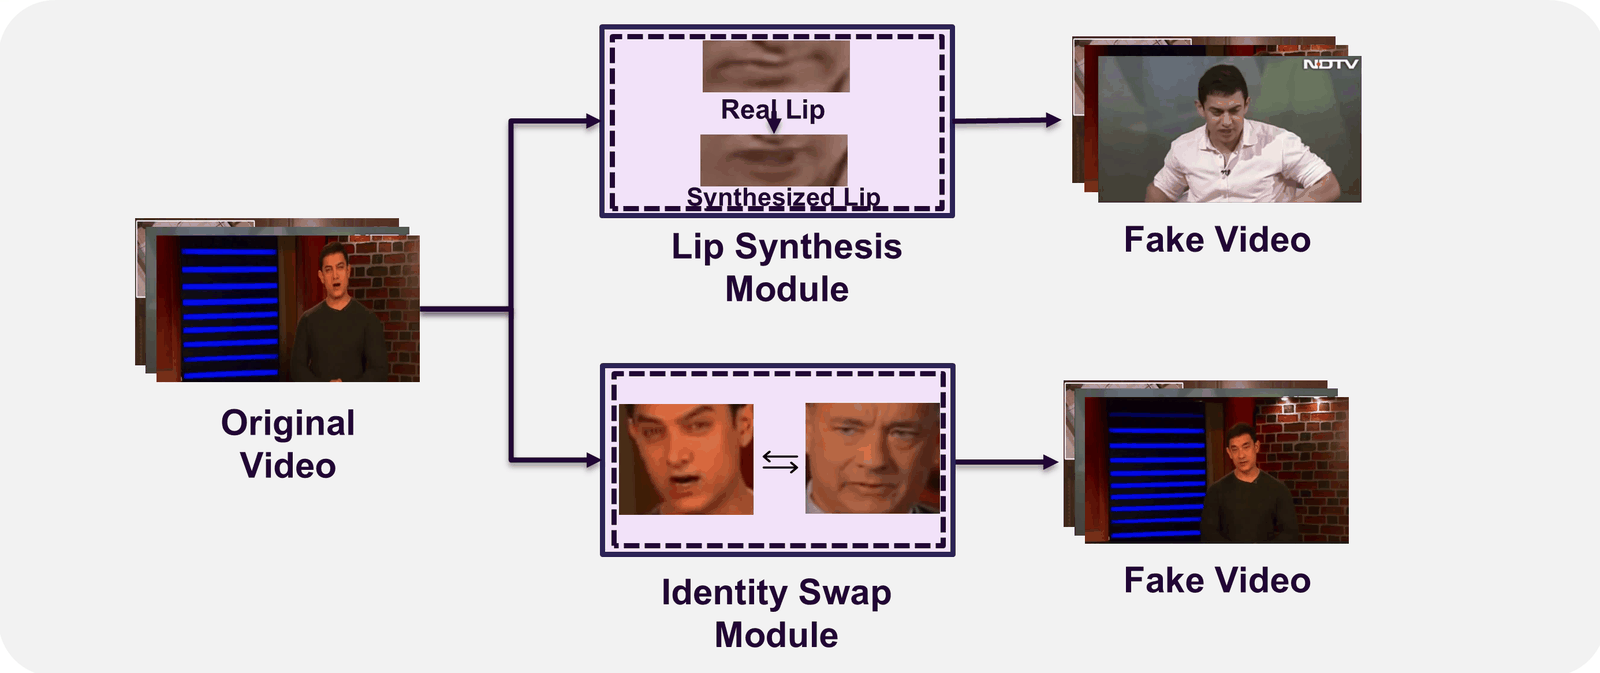
Step 0: read the speech without audio
- Auto-AVSR (visual speech recognition, VSR) transcribed each silent video from lip movements.
- VSR is less accurate than audio speech recognition, so we reviewed the transcripts.
- Unreliable text or too little speech → identity-swap branch (154 videos, 26.1%).
- All others → lip-synthesis branch (436 videos, 73.9%).
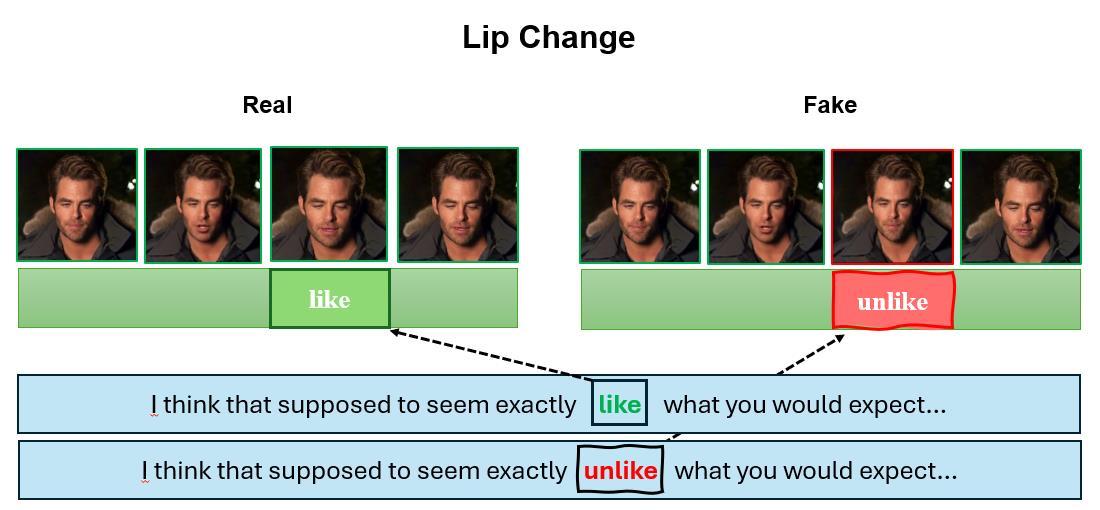
Lip-synthesis branch (436 videos)
- An LLM (Claude Sonnet 4) replaces at least 3 key or emotion words with opposite or contrasting words.
- Kokoro TTS turns the edited script into speech (WAV).
- MuseTalk generates lip motion for the new speech while keeping the speaker's face identity.
- Montreal Forced Aligner returns the start and end time of every word.
- Only the frames of the changed words are swapped with the synthesized ones.
A행동
0단계: 오디오 없이 발화 읽기
- Auto-AVSR(시각 음성 인식, VSR)로 무음 영상의 입 모양에서 발화 텍스트를 추출했습니다.
- VSR은 오디오 기반 음성 인식보다 정확도가 낮아, 추출된 텍스트를 검토했습니다.
- 텍스트가 부정확하거나 발화가 부족한 영상 → 얼굴 교체 브랜치 (154개, 26.1%).
- 나머지 → 입술 합성 브랜치 (436개, 73.9%).
입술 합성 브랜치 (436개)
- LLM(Claude Sonnet 4)이 핵심 단어나 감정 단어를 3개 이상 반의어·대조 어휘로 바꿉니다.
- Kokoro TTS가 수정된 스크립트를 음성(WAV)으로 만듭니다.
- MuseTalk이 화자의 얼굴 신원을 유지하면서 새 음성에 맞는 입 모양을 생성합니다.
- Montreal Forced Aligner가 단어별 시작·종료 시각을 찾습니다.
- 바뀐 단어 구간의 프레임만 합성 프레임으로 교체합니다.
A行动
第 0 步:在没有音频的情况下读出台词
- 用 Auto-AVSR(视觉语音识别,VSR)从唇部动作中转写每个无声视频。
- VSR 的准确率低于基于音频的语音识别,因此我们检查了转写文本。
- 文本不可靠或台词太少 → 换脸分支(154 个视频,26.1%)。
- 其余 → 唇形合成分支(436 个视频,73.9%)。
唇形合成分支(436 个视频)
- LLM(Claude Sonnet 4)把至少 3 个关键词或情感词替换为反义或语境相反的词。
- Kokoro TTS 把修改后的脚本转成语音(WAV)。
- MuseTalk 在保留说话人身份的同时,生成与新语音匹配的唇形。
- Montreal Forced Aligner 给出每个词的起止时间。
- 只把被改词语对应的帧替换为合成帧。
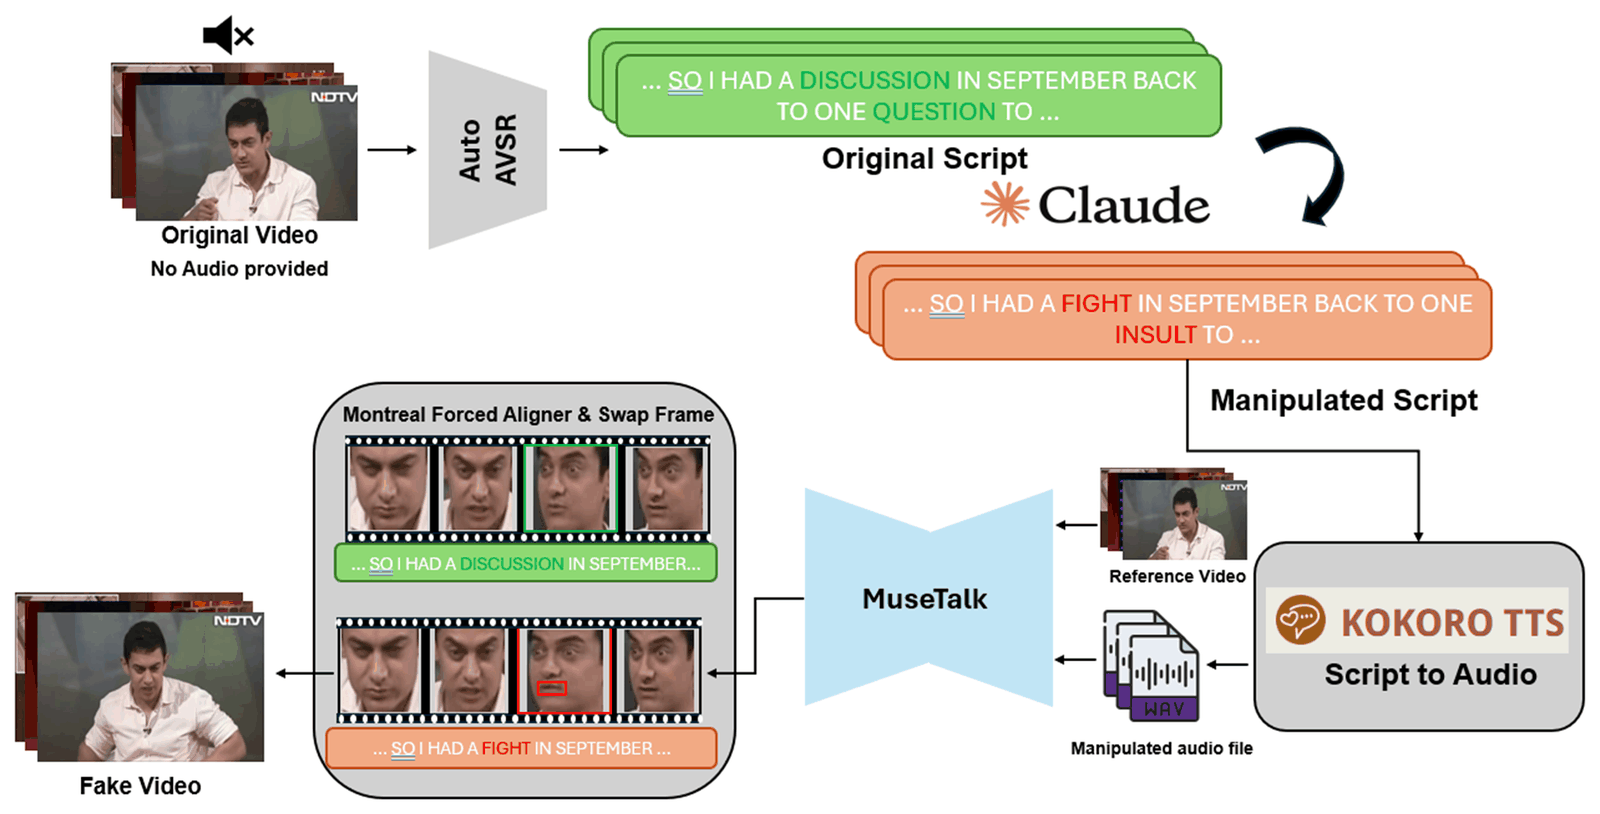
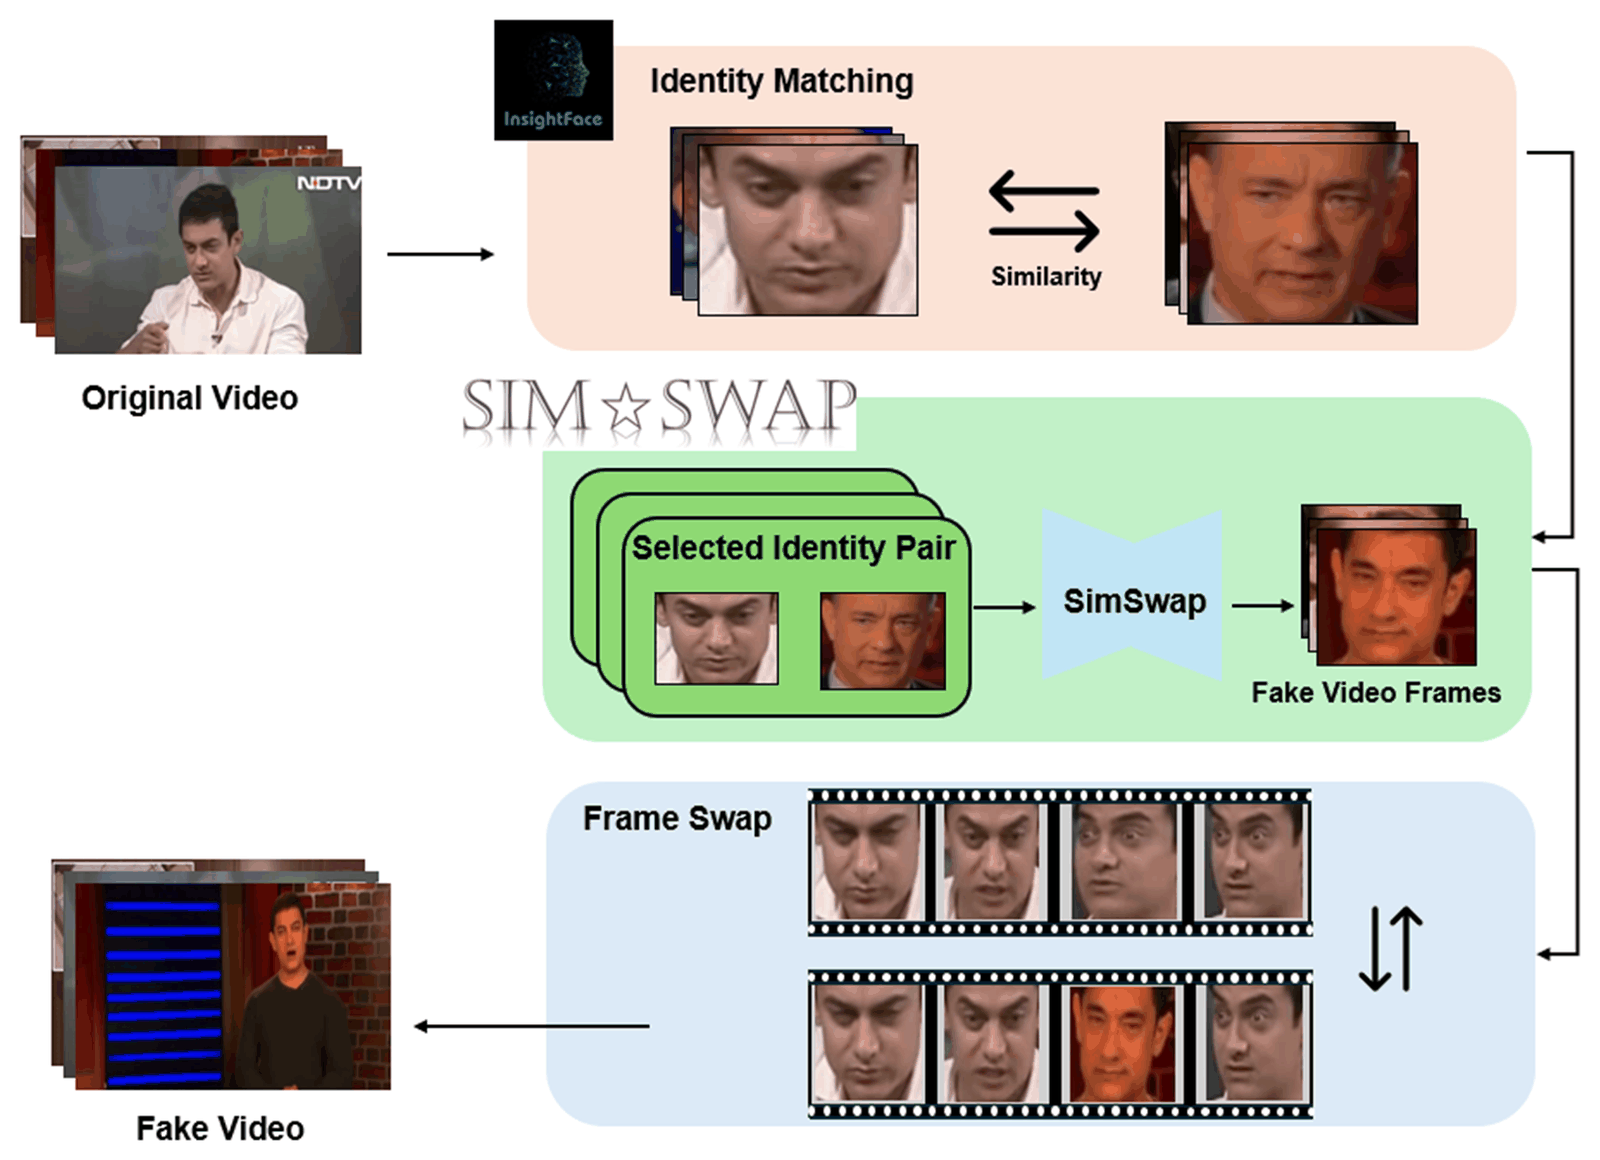
Identity-swap branch (154 videos)
- InsightFace detects and crops the face in every frame.
- ArcFace turns each face into a 512-dimensional identity embedding.
- Cosine similarity picks representative frames and drops low-quality or duplicate candidates.
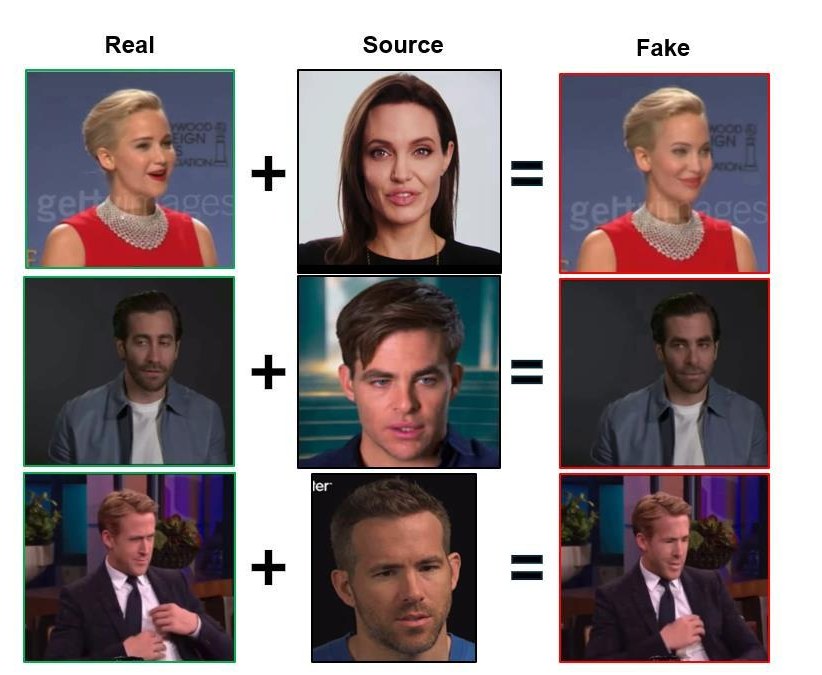
- SimSwap puts the source identity on the target face. It keeps expression, gaze direction and head angle.
- 1–3 swapped segments of 15–45 frames (about 0.5–1.5 s) replace the same spans of the real video.
- Why 15–45 frames: the length matches natural motions such as lowering or turning the head, coughing, or covering the face.
- Segments are spaced apart, so the edits do not form a repeated pattern.
얼굴 교체 브랜치 (154개)
- InsightFace로 모든 프레임에서 얼굴을 검출하고 잘라냅니다.
- ArcFace가 각 얼굴을 512차원 신원(identity) 임베딩으로 바꿉니다.
- 코사인 유사도로 대표 프레임을 고르고, 품질이 낮거나 중복된 후보는 버립니다.
- SimSwap이 소스 신원을 타깃 얼굴에 입힙니다. 표정, 시선 방향, 고개 각도는 유지됩니다.
- 15–45프레임(약 0.5–1.5초) 길이의 교체 구간 1–3개로 실제 영상의 같은 구간을 바꿉니다.
- 15–45프레임인 이유: 고개를 숙이거나 돌리기, 기침하기, 손으로 얼굴 가리기 같은 자연스러운 동작 길이와 맞습니다.
- 구간 사이에 충분한 간격을 두어, 조작이 반복 패턴으로 드러나지 않게 했습니다.
换脸分支(154 个视频)
- InsightFace 在每一帧中检测并裁剪人脸。
- ArcFace 把每张人脸转换为 512 维身份(identity)嵌入。
- 用余弦相似度挑选代表性帧,剔除低质量或重复的候选。
- SimSwap 把源身份换到目标人脸上,同时保留表情、视线方向和头部角度。
- 用 1–3 段、每段 15–45 帧(约 0.5–1.5 s)的换脸片段替换真实视频中的相同区间。
- 为什么是 15–45 帧:这一长度与低头、转头、咳嗽、用手遮脸等自然动作的时长相符。
- 片段之间留有足够间隔,避免篡改形成重复模式。
RResult
- Excellence Award (우수상), Korean Institute of Information Scientists and Engineers (KIISE), Jul. 2025.
- All 590 source videos were turned into partial deepfakes: 436 by lip synthesis and 154 by identity swap.
R결과
- KIISE(한국정보과학회) 우수상, 2025년 7월.
- 원본 영상 590개를 모두 부분 조작 딥페이크로 만들었습니다: 입술 합성 436개, 얼굴 교체 154개.
R结果
- KIISE(Korean Institute of Information Scientists and Engineers)优秀奖(우수상),2025年7月。
- 590 个原始视频全部制作成局部篡改深度伪造:唇形合成 436 个,换脸 154 个。